
 koala73/worldmonitor88k
World Monitor
Live markets, conflicts, country risk, chokepoints, energy, and China decision signals. 90 tools.
AI 与智能体

Measure token savings per AI coding agent, optimize context, and share a live local knowledge graph across 16 CLI clients.

Compression that optimises your bill, not your byte count — and ships the benchmark so you can check it.




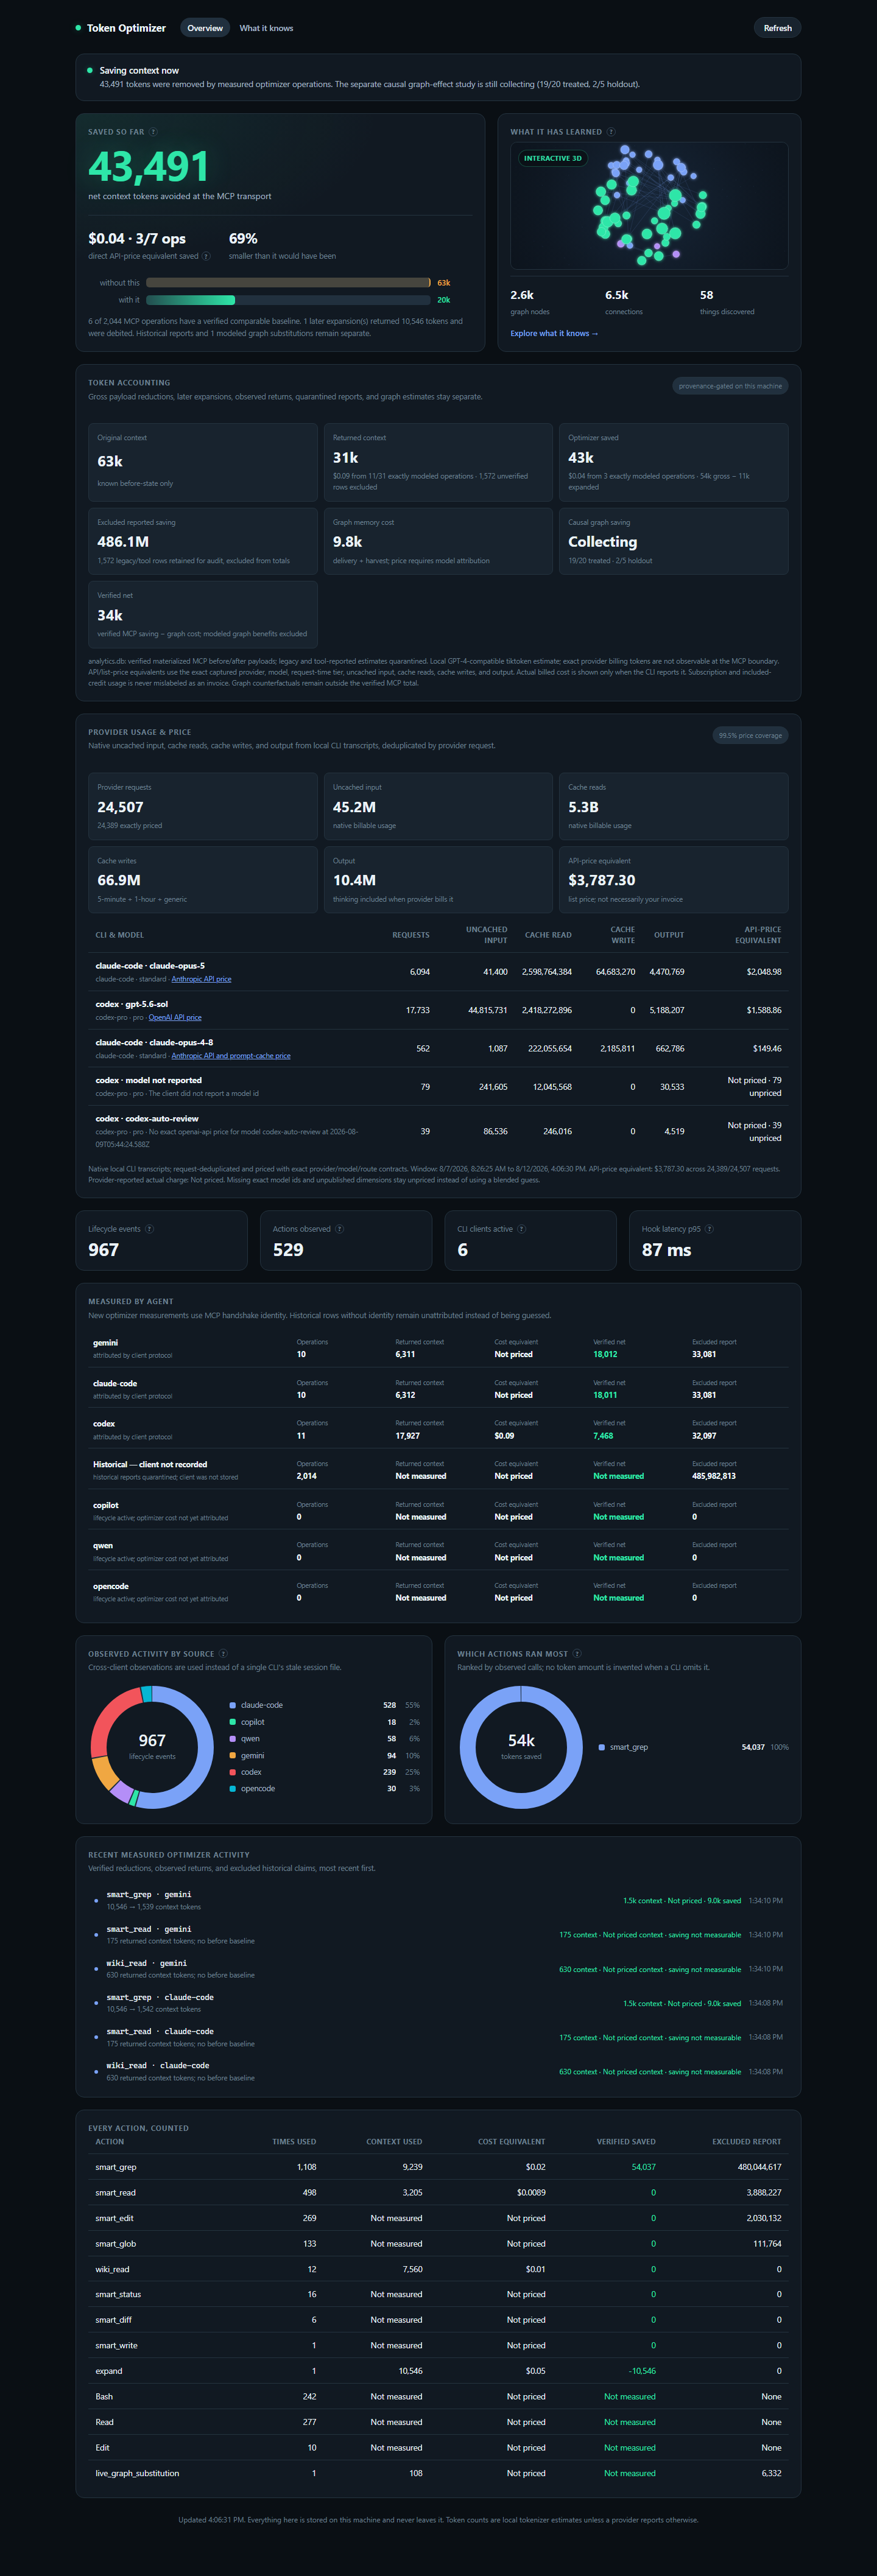
One local ledger for optimizer tools, live-graph substitutions, every agent, and the graph's own cost.
Providers cache the prompt prefix: cached tokens re-read at 0.1x, rewritten ones bill at 1.25x. Most compressors optimise bytes removed and ignore that multiplier. This one optimises the bill.
It wins both columns, against their real implementation, on their own fixtures. Not a reimplementation and not our fixtures: their harness compresses the payload, dumps it, their resolver redeems their own markers, and ours is handed the identical bytes.
| workload | payload | theirs | ours | ours, preset | ours, dial on | zero-turn ids |
|---|---|---|---|---|---|---|
| agent-loop | 172,110 | 41.9% / 46.7% | 93.8% / 94.7% | 93.8% / 94.7% | 100.0% / 100.0% | 69 / 254 / 69 |
| agent-loop-logs | 328,490 | 51.3% / 45.8% | 96.3% / 97.1% | 96.3% / 97.1% | 100.0% / 100.0% | 87 / 2042 / 87 |
| browser-session | 782,294 | 21.8% / 13.6% | 93.7% / 28.9% | 100.0% / 99.9% | 100.0% / 99.9% | 336 / 336 / 0 |
| code-search | 131,444 | 47.5% / 53.5% | 95.8% / 96.5% | 95.8% / 96.5% | 99.9% / 99.9% | 65 / 470 / 65 |
| codebase-exploration | 136,113 | 99.7% / 99.6% | 65.1% / 58.0% | 100.0% / 99.9% | 100.0% / 99.9% | 509 / 5 / 0 |
| grep-output | 75,399 | 99.6% / 99.6% | 57.4% / 52.8% | 99.9% / 99.9% | 99.9% / 99.9% | 1046 / 4 / 0 |
| human-authored-json | 38,645 | 32.8% / 31.3% | 96.9% / 97.2% | 96.9% / 97.2% | 99.8% / 99.9% | 18 / 174 / 18 |
| issue-triage | 109,534 | 53.1% / 54.4% | 95.3% / 95.9% | 95.3% / 95.9% | 99.9% / 99.9% | 34 / 504 / 34 |
| raw-build-log | 158,237 | 99.8% / 99.8% | 70.7% / 47.7% | 100.0% / 100.0% | 100.0% / 100.0% | 430 / 3 / 0 |
| relevance-probe | 49,367 | 64.3% / 65.4% | 96.1% / 97.0% | 96.1% / 97.0% | 99.9% / 99.9% | 24 / 527 / 24 |
| repeated-reads | 152,321 | 22.8% / 20.5% | 74.3% / 69.7% | 100.0% / 100.0% | 100.0% / 100.0% | 361 / 405 / 0 |
| sre-debugging | 312,456 | 88.4% / 90.5% | 97.1% / 97.7% | 97.1% / 97.7% | 100.0% / 100.0% | 89 / 514 / 89 |
Recorded 2026-09-25 at 18a2d085, by the command in the
record's regenerate field. That second arm runs HeadRoom itself, so CI does not
re-derive it the way it re-derives the table below -- it checks this provenance and
these figures against bench/compression/headroom/results/head-to-head.json instead.
Over the corpus the shipped default takes 89.4% of the characters and 80.9% of the tokens; theirs takes 51.3% and 62.8%. Of the 9,919 identifiers planted in the corpus, 45 end up unrecoverable on our side and 8 on theirs.
Read the rows, though, because the ones we lose are not compression
results. On grep-output, codebase-exploration and raw-build-log they
report ~99.7% and we report 57-71%. Their number there is a content-cache
reference: the block is not made smaller, it is taken out of the request, put
in a store, and replaced by a 24-character <<ccr:...>> marker. The same is true
of the four rows where they edge us out in the nineties.
So the last column is the one that decides a turn. A marker is not the
content: to read what it stands for, the agent spends a request. zero-turn ids
counts the identifiers planted in each workload that need no such request --
still in the text, or rebuildable from the text alone. On the three rows we
lose on reduction we take that column outright, 509-5, 1046-4 and 430-3: their
marker leaves almost none of it behind, our skeleton leaves all of it. We lose it on
eight rows -- agent-loop, agent-loop-logs, code-search,
human-authored-json, issue-triage, relevance-probe, repeated-reads and
sre-debugging -- because our reduction there comes from spilling too, and a
spill costs the same turn theirs does; browser-session ties at 336-336. Over
the corpus it is 3,068 of 9,919 for us against 5,238 for them: this column
goes to them, and the two columns have to be read together or each one
flatters somebody.
The unit count moved with the instrument, not with the product. Every rule that
found a retention unit keyed on a digit-bearing token, a markdown heading or a
declaration, so issue-triage ("number": 3000) and relevance-probe
("id": "evt_0", the needle that workload exists to find) each scored ZERO
units and reported a tie on an empty set. Counting a string value under an
object key and a quoted substring inside a longer string -- on both arms, and
excluding multi-line values, which are not literal substrings of the block they
came from -- takes the corpus from 6,098 units to 9,919 and reverses this
column, which read 2,717 against 2,278 before the fix.
browser-session used to be the one genuine engine loss on this corpus, at 6.0%
against their 21.8%. It is now 93.7%, from folding exact long repeats inside a
block rather than at a boundary someone else drew — a serialised message
list with inline images is a single 780,000-character line, which every other
pass here reads as one unit.
Most of that 93.7% is the fixture, and the honest number is lower. This payload holds four images, two of them distinct, and the base64 in them is generated rather than photographic: one distinct image alone folds from 160,032 characters to 5,572, which no real PNG would do. What carries over to a real session is the duplication — half the image bytes here are a second copy of an image already in the request, which is 44.3% of the whole payload, and an agent re-sending a screenshot it has already sent is ordinary. Folding only that is a ~44% reduction, still ahead of their 21.8% on the same row, and the generated base64 is worth about 49 points on top that we would not claim twice.
The run the marker names is still in the output above it, so the reader rebuilds it without asking for anything, which is why the characters fall much further than the tokens (28.9%) — the image tokens are counted from pixels on both arms either way.
ours, dial on is that like-for-like, and it is substitution, not reduction.
Set spillWholeBlockBelow and a block our engines could not compress is moved
out of the request whole, leaving [... n bytes, moved whole -> path]. It wins
all twelve rows on both denominators, but nothing there was compressed: the bytes
are on disk, at 1.00x the input, and the ratio is a measurement of a move.
Any quote of that column that omits this sentence is a misquote.
Two things make it the better version of their trade, which is the only reason
it exists. It is gated on the saving our engines actually reached, not on
block size, so a block we compressed well stays in the request where the reader
still has it — a content cache moves it regardless. And the marker carries a
path the agent already has, so following it is a Read it issues itself,
where a cache reference costs a retrieval round trip and degrades to
[unresolved: entry not found] once the store has moved on.
It is off by default, because the trade is real: every one of the 2,334 identifiers a reader can rebuild from our output with no extra turn sits in exactly the blocks it would move -- the five rows where the dial fires are the five rows that reconstructible column lives on, and nowhere else. On by default, this would be their product with a better marker.
ours, preset is the same dial at the setting a caller would actually run
-- spillWholeBlockBelow: 0.9, so a block is moved only where the engines could
not take 90% off it. On seven of the twelve rows it changes nothing at all: the
figure is the shipped one, the block stays in the request, and the zero-turn
count is untouched. On the other five it matches their headline -- 100.0% on
codebase-exploration, 99.9% on grep-output, 100.0% on raw-build-log -- and
it buys that the same way they do. Those five rows are exactly where our
zero-turn wins live, and the column takes all of them: 509, 1046, 430, 361
and 336 go to 0. Over the corpus it is 98.1% of the characters against 89.4%, and
386 zero-turn identifiers against 3,068. It also puts 46 identifiers beyond
anything in the output, against 45 shipped -- but a moved block is a turn, and the preset
column is published so that trade is visible rather than folded into a
headline. It is off by default for the same reason.
Reproduce the whole table:
python bench/compression/headroom/run-theirs.py <headroom-clone> <out-dir>
python bench/compression/headroom/resolve-theirs.py <headroom-clone> <out-dir>
node bench/compression/head-to-head.mjs <out-dir>
A second arm reimplements their published design from their own benchmark
generator's definitions — opaque hash markers, history compressed, a retrieval
tool and system message injected — so the four workloads with a published
comparator can be checked without their clone. node bench/compression/proof.mjs:
| workload | payload | theirs | ours | verdict |
|---|---|---|---|---|
| code-search | 17765 | 92.1% | 97.8% | ours |
| sre-debugging | 65694 | 92.2% | 98.6% | ours |
| issue-triage | 54174 | 72.8% | 97.5% | ours |
| codebase-exploration | 78502 | 47.4% | 53.7% | ours |
Four workloads, because those are the four this arm has a published comparator for. The harness reports twelve; the other eight are ours alone here, and are scored head-to-head in the table above instead.
codebase-exploration was theirs and is now ours, by 16.8 points. An earlier
version of this table claimed 61.3% for us on that row, then parity, then a
published loss at 46.0% against their 47.4%. The first two were figures from a
branch rather than from here; the third was true on this tree when it was
written; four log engine commits then moved it to 54.2%, masking an interior
hashbang so a concatenated block still parses moved it to 64.9%, and
authenticating every marker with a six-character stamp took 0.2 of a point
back, and naming a spilled file by a digest of its contents, the way the proxy
sink really names it, instead of by its position in a counter, took another
half point, to reach 64.2%. Then the currency stopped being an estimate: every
figure in the table above is now the count Anthropic's own tokenizer returns
for the text, recorded into a committed fixture so this stays offline, and
under it the row reads 53.7%. That is the largest move in this history and
the only one that is not about the engine at all. Dividing characters by four
had been charging the control's hex markers too much and our own stamp far too
little -- the stamp was six characters of a vowelless base-31 alphabet then,
and a random string over a large alphabet is close to the worst case a BPE
tokenizer has, so it cost a measured 5.52 tokens where chars/4 billed 2. Those
three are the only figures here that moved the wrong way, and none of them is a
regression: each is the harness charging us for something it had been leaving
out. Being able to see that cost is what paid for the next move: the stamp is
now nine decimal digits, which carry slightly more entropy than those six
characters did and cost 4 tokens on every draw rather than a mean of 5.52 that
ranged from four to seven. Measured against the old stamp on this row -- the
same tree, the same fixture, only the stamp pinned back to its base-31 form --
that bought a tenth of a point, and a tenth is the honest size of it: a
marker got better than a quarter cheaper, but markers are a small part of what
the engine emits, so the headline moves far less than the per-marker saving
suggests. A
number in prose is a fact about the tree it was measured on, which is why
bench/compression/readme-table.check.mjs re-derives every figure in the block
above from the harness rather than trusting it.
Reduction is not the only column, and the other one goes to them. Scored
symmetrically on their own fixtures, of 9,919 retention units they keep
5,238 directly visible in the text they send and we keep 734 — we reach
a higher reduction partly by eliding harder, into a spill about 0.44x the size
of the input. A further 2,334 of ours are reconstructible from the output
alone with no extra turn, and 6,806 are behind a path in the output, one
Read away; theirs redeems 4,673 through its store, one retrieval call away.
45 are unrecoverable on our side and 8 on theirs. All of those numbers belong in any
quote of any of them.
Against the four comparators in this reimplemented arm: ours on all four. Against their real implementation on all twelve workloads, the table at the top of this section: ours on 9 of 12 by default, 12 of 12 with the dial on, and ours on the corpus total in both denominators either way. Their column is the best of the nine configurations that capture holds, and on the seven rows they take it is the content-cache reference described above rather than a smaller block — which is why the dial, doing the same kind of thing, takes all twelve.
The two columns come from different arms of the same engine, and that is the
point. v3-history compresses history too and matches them byte for byte;
v1-frontier leaves the cached prefix alone and wins the invoice by 11–42%.
Maximising bytes removed is available and is not the default, because on a
cached prefix it costs money.
The competitor arm is this repository's reimplementation of their published design — opaque hash markers, history compressed, a retrieval tool and system message injected — not their binary, and it is held to the same signed-content guard we hold ourselves to.
node bench/compression/session-replay.mjs replays real recorded conversations
turn by turn and prices each the way a provider does. Four independent sessions,
whole request including system prompt and tool schema, against no proxy:
| conversation length | ours | cheaper on |
|---|---|---|
| 10 turns | 0.953x | 4 of 4 |
| 20 turns | 0.915x | 4 of 4 |
This is the region nothing else touches: conversation history is ~65% of a live request and the only part that grows every turn. The saving grows with session length, because model reasoning accumulates.
THOL, 16 real tasks against a no-proxy control:
One run per task, so the aggregate interval still spans 1.0; the per-task tally and the score parity are the solid parts. Every figure here is regenerated from the committed benchmarks, which ship in this repository.
Your agent burns most of its context on work it already did: re-reading files that have not changed, dumping a whole file to see three lines, running unbounded searches, and re-deriving conclusions it reached last session and then forgot.
Token Optimizer attacks that on four fronts.
1. It makes the expensive call impossible. Install the plugin and a built-in
Read of a 200 KB file is denied, with the refusal naming the cached,
diffed replacement. Same for Grep, Glob, Edit, Write, and cat /
head / grep -r through the shell. Re-reading a file you already read this
session returns only a diff — usually the single biggest win, and one that
size-based rules structurally cannot catch. There is no setting to turn on.
2. It remembers what your agent worked out. A per-project knowledge graph accumulates findings, decisions and dead ends as a side effect of working, then feeds them back the moment the agent touches the relevant file. A finding costs ~150 tokens to carry. Re-deriving it costs 5k–50k.
3. It measures itself, in public, and tells you when it is losing. A materialized before/actual-return measurement for MCP progressive disclosure, with later expansions debited from the same net. Modeled graph substitutions and the randomized control arm for downstream graph effects remain separate. Every number is measured, visibly collecting, excluded, or absent.
4. It attributes the traffic. Returned context, optional cost equivalents, and net transport avoided are grouped by operation and MCP handshake identity. Codex, Claude Code, Gemini, and any other connected client get separate rows. Old records without identity remain explicitly unattributed instead of being assigned to whichever agent happens to be open now.
No account and no hosted service. MIT, so it is usable at work.
Nothing is measured about you unless you ask for it. Anonymous usage data is
off by default and takes two separate opt-ins: TOKEN_OPTIMIZER_TELEMETRY=1
aggregates counts into a file on your own disk, and TOKEN_OPTIMIZER_BEACON=1
is what uploads any of it. Setting the first opens no socket. With both set,
the events already on disk are sent once per session at start-up -- in a batch,
never on the hot path -- and the file is cleared only after the receiver has
accepted them. install_doctor prints which of the two is on, how many events
are waiting and where they would go; it reports without sending. A package
built without the upload key cannot transmit at all, and the doctor says so
rather than letting an opt-in look like it is working.
DO_NOT_TRACK=1 overrides both, whatever else is set. The version check
npm run doctor and install_doctor make is a plain GET to the registry npm
installs from, carries nothing about you, and runs only when you ask for a
diagnosis -- never during a session. DO_NOT_TRACK=1 or
TOKEN_OPTIMIZER_UPDATE_CHECK=0 suppresses it before a socket is opened. An event may only
contain numbers and flags -- a string is dropped before it is written, so a
path, a prompt or an error message cannot travel even by mistake -- and the
machine identifier is a salted hash, never your hostname. What the counts are
about is the hook ledger your own project already keeps: how often the graph
answered instead of a tool, what each arm of the holdout was delivered and
withheld, and whether the saving exceeded the cost -- reduced to integers once
every six hours, never the ledger itself, which names your files. Usage is
counted as a rollup rather than a row per request: one event per 200 requests,
holding the request count, bytes in and out, how often compression paid, how
often knowledge was injected, and how many blocks were elided, plus one final
event when the proxy stops. That keeps the totals exact -- a row per request
would overflow the batch on a busy session and leave you reporting its first
five hundred -- at the cost of the per-request distribution, which is not
something anyone downstream needs. npm run doctor
prints exactly which of these is on and what has been recorded.
The screenshots in this README come from the shipped server reading persisted local data, not a design mockup. In the capture above it reports:
Collecting.The dashboard now reads native CLI usage receipts and prices uncached input, cache reads, cache writes, and output with the exact captured provider, model, route, request-time tier, and versioned official source. Ambiguous model ids stay Not priced instead of receiving a blended guess. API/list-price equivalents are kept separate from provider-reported charges and are never labeled as a subscription invoice. See the token accounting contract.
Claude Code — install the plugin, not the bare MCP server. The plugin is what enforces; adding the server alone just gives the model tools it can ignore.
/plugin marketplace add ooples/token-optimizer-mcp
/plugin install token-optimizer@token-optimizer
/reload-plugins
That is the entire installation. All sixteen clients →
Then, whenever you want to know what to do next:
token_audit
One ranked queue: what is costing the most per session, with an optional monthly cost equivalent only after you configure your own effective rate. Each line names how to fix it. Not a dashboard, not six reports — a queue.
Every agent session ends the same way: the reasoning evaporates. The next session re-derives it, at full price, forever.
This builds a living per-project graph — nodes for files, symbols, tasks and
findings; edges for derived_from, contains, supersedes, contradicts,
related — and it fills itself in from real work. No ingestion job, no
embedding model, no rebuild step, no query to formulate.
you touch  src/auth.ts
           │
           ├─ verify() compares exp against the LOCAL clock          (finding, 0.9)
           ├─ per-host retry budgets; global was rejected — deadlock (decision)
           ├─ ! the skew fix was reverted once already               (dead end)
           └─ [git] 47 changes in 90d, last three: "fix token expiry",
                    "revert skew fix", "fix token expiry again"
None of that is in your repository. It exists only because an agent once burned tokens finding it out — and every other tool throws it away at the end of the session.
What a default install actually produces. The structural graph — files,
symbols, tasks, and the edges between them — is captured from ordinary tool
traffic with no configuration at all. Findings are produced two ways. At session
end, derive reads evidence already on disk (command outcomes and exit codes,
red-to-green transitions, corrections, re-read churn) and writes findings from
it: no model call, no credential, nothing sent anywhere. And the active model
records durable conclusions itself through wiki_write.
The model-based semantic harvest is the third path, and the only one that
needs something you do not already have. It is not opt-in —
TOKEN_OPTIMIZER_HARVEST=0 turns it off — but its real gate is a credential:
with none it reports off:no-key, which is the state on CI, corporate machines,
and subscription-only logins. Point TOKEN_OPTIMIZER_HARVEST_ENDPOINT at a
local model and it runs free and private, with nothing leaving the machine.
npx token-optimizer-doctor states which of these is live.
| Classic RAG | This |
|---|---|
| Retrieves evidence; the model re-derives meaning each time | Retrieves verdicts — the reasoning already happened |
| Index built by a batch ingestion job | Accretes from real agent traffic — coverage follows attention |
| Similarity search | Traversal — this symbol and its callers |
| Model must formulate a query | Fires when the model reaches for a file |
| Staleness invisible; serves rotted chunks confidently | Staleness computed from content hashes, served with the invalidating diff |
| Returns only what is in the documents | Returns dead ends, which exist nowhere in your source tree |
Traversal plus lexical search: deterministic, instant, explainable, and it works offline.
A plain deny costs a full turn: the model calls Read, is refused, re-plans,
calls smart_read. But at refusal time we already hold the file and the
snapshot the graph stored — so the refusal carries the answer inside it.
Nothing to re-plan, no second call. Turn cost drops from one to zero.
And when the graph already holds the verdict a tool output would support, the output never enters context at all. Not compressed. Absent.
npm install
npm run build
npm run dashboard      # http://localhost:3100
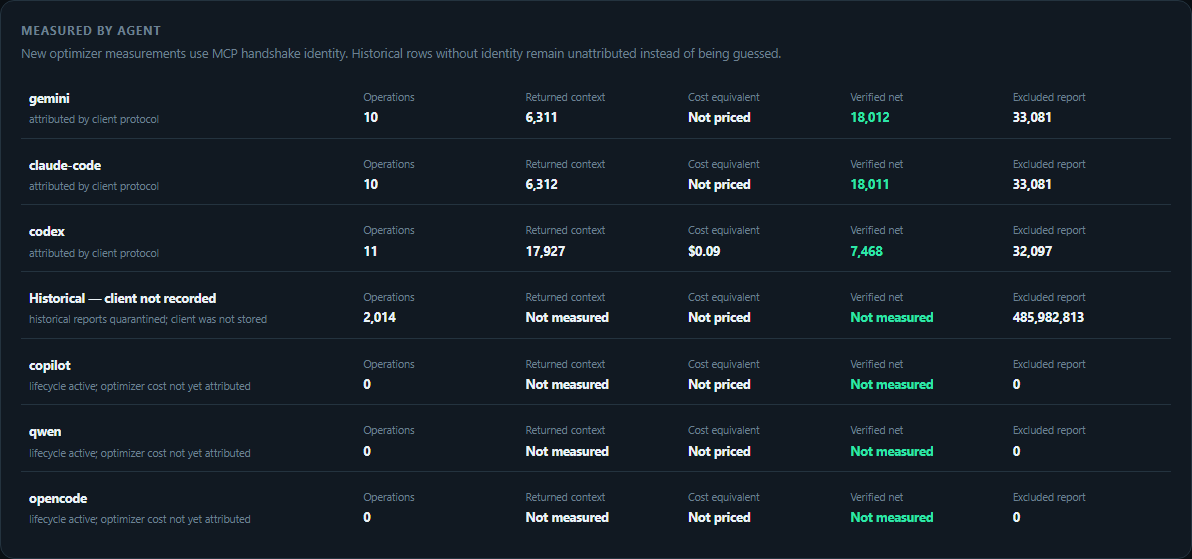
The overview answers the questions a token optimizer should answer first:
Not measured; no zero is invented.smart_read, smart_grep, smart_glob, smart_edit, or any other MCP
operation normally. Every successful result records returned context; tools
with a comparable materialized before-state also record a gross reduction;
later expand calls debit that reduction.wiki_write. Before a
new agent re-derives work, call wiki_read for the project or the files it is
about to touch. Native clients can also deliver matching knowledge
automatically.
Use wiki_query to read the graph directly — one finding by key, a ranked
BM25 search over claims, a node with its neighbours, or the graph's own audit
— which is how a subagent that never sees the SessionStart briefing reaches
what previous sessions established.http://localhost:3100. Use Overview for combined accounting and
What it knows for capture health, graph exploration, audits, and causal
evidence.npm run projects:discover -- /absolute/path/to/repos. This makes coverage
gaps explicit; it does not fabricate findings.For maintainers, this live smoke exercises the shipped stdio transport and creates separately attributed rows without seeding the analytics database:
npm run dashboard:attribution-smoke -- /absolute/path/to/project /absolute/path/to/large-file
npm run dashboard:verify-live -- http://localhost:3100
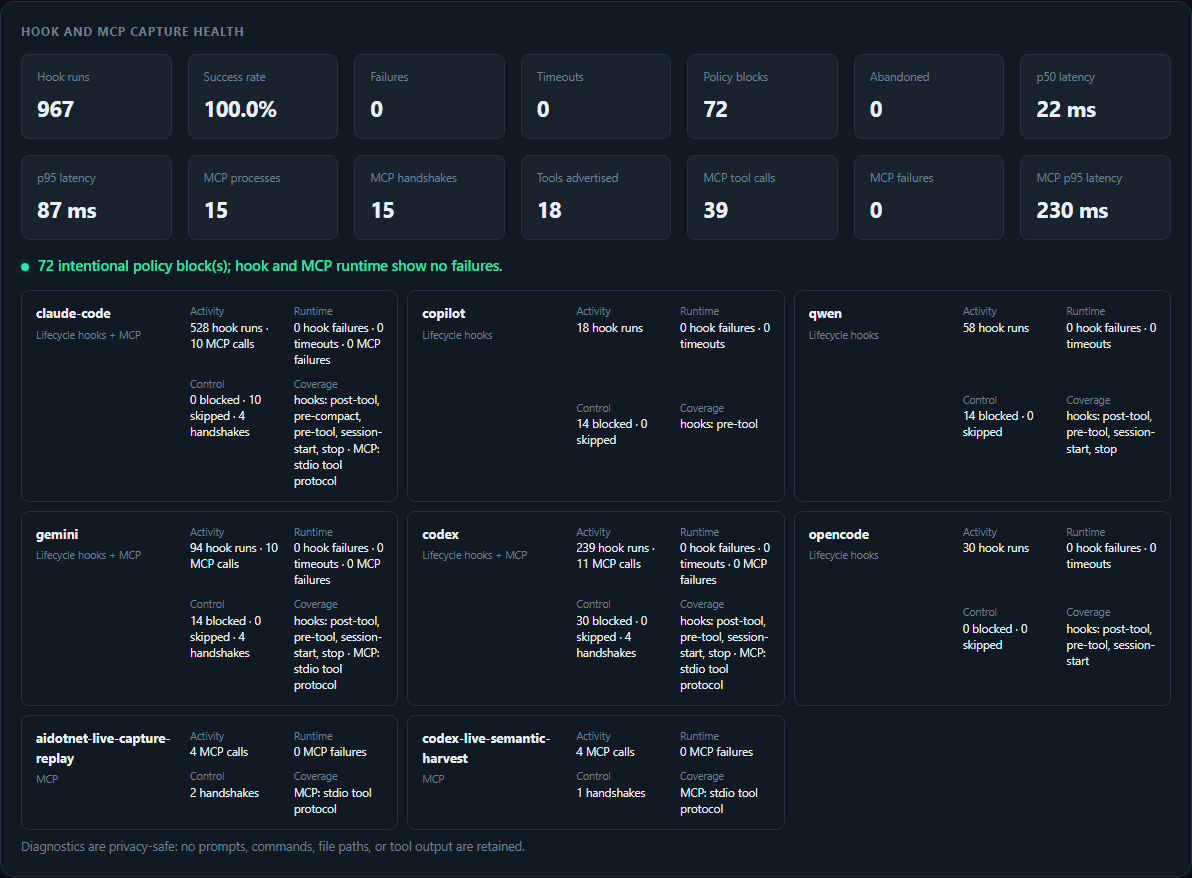
The health panel is deliberately operational rather than a raw text dump. Each client has activity, runtime failures/timeouts, policy outcomes, and observed surface coverage. Diagnostics keep no prompts, commands, paths, or tool output.
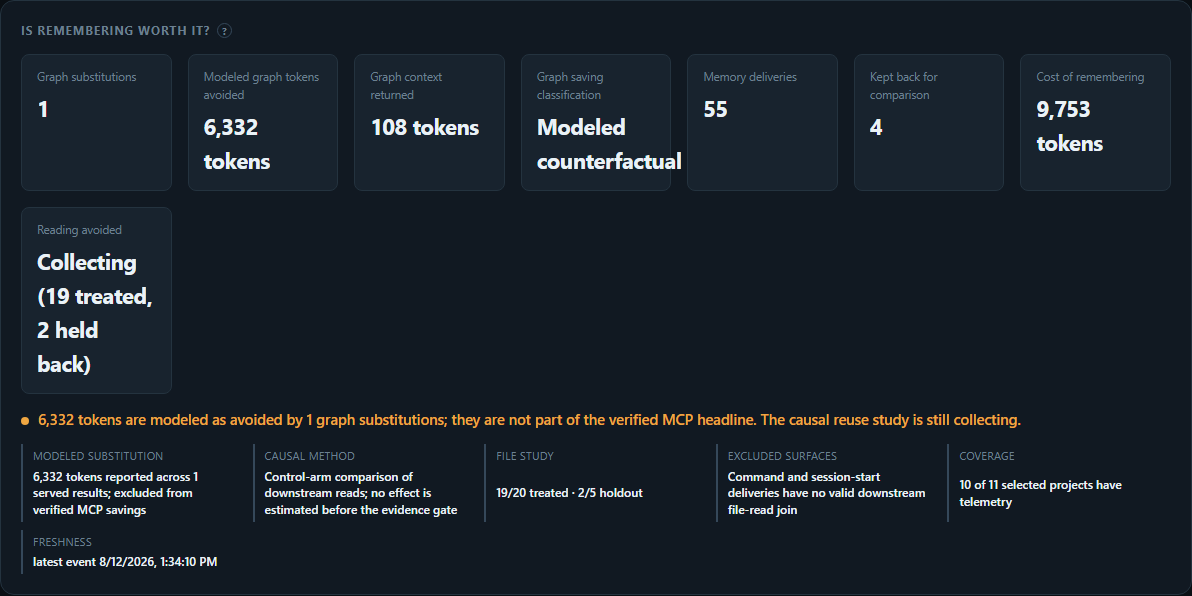
Modeled substitution potential and causal graph effects are different claims.
The first is a full-file counterfactual and is never promoted to the verified
MCP headline. The second asks whether delivered knowledge prevented later reads;
it uses a control arm and remains Collecting until there are at least 20
treated file touches and 5 holdouts with valid downstream joins.
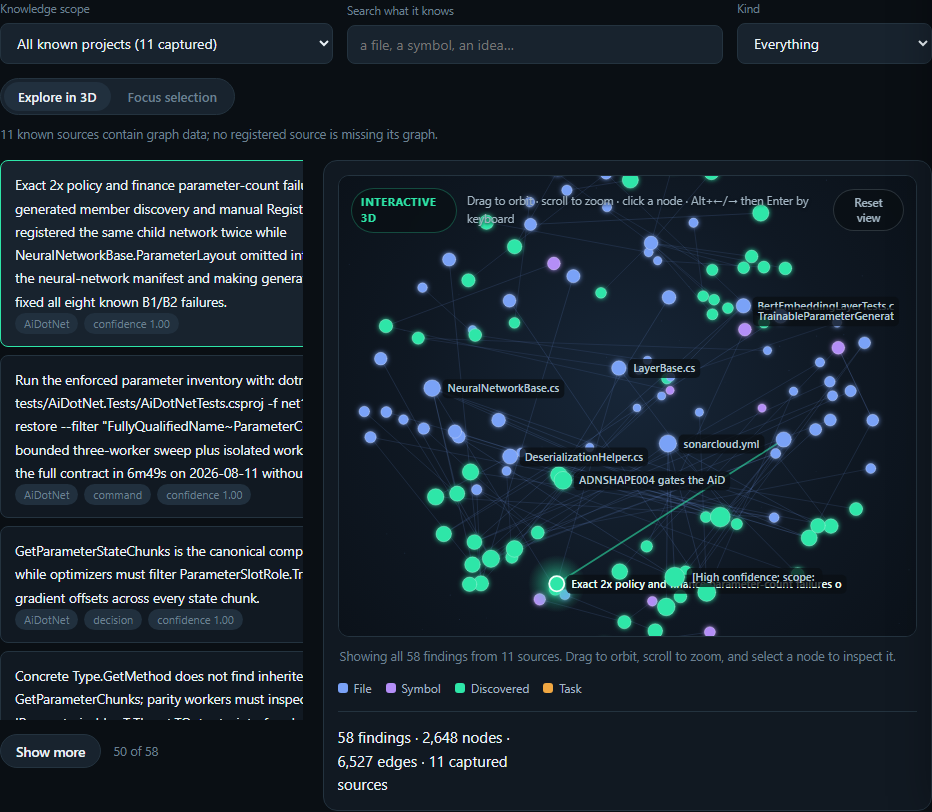
Drag to orbit, scroll to zoom, click a node for provenance, or switch to the bounded one-hop focus view. The default All known projects scope pools local graphs through opaque project IDs; filesystem paths never reach the browser.
Audit tab. Contradictions, stale findings, and low-confidence claims remain reviewable instead of silently becoming model truth.
Evidence console. Client/model/task cohorts, matched effects with 95% intervals, live outcome joins, harm feedback, and capability tiers for all 16 clients. Release and superiority claims fail closed while evidence is missing.
One-click Markdown export. The accumulated graph becomes documentation you can inspect, edit, and commit.
Server-side by design: the browser asks for a neighbourhood, a search result or a page. A mature graph holds thousands of nodes, and shipping it wholesale would make every page load a multi-megabyte download for a view that shows twenty things.
The default All known projects scope combines captured graphs through an opaque machine-local project registry; filesystem paths never reach the browser. Lifecycle hooks register repositories as they are used. To backfill existing local checkouts without reading their source files, run the bounded discovery command against one or more explicit roots:
npm run projects:discover -- /absolute/path/to/repos /absolute/path/to/worktrees
Coverage distinguishes repositories with graph data from known repositories
whose capture has not started. The balance cards are backed by persisted events:
Memory deliveries counts graph context actually supplied to an agent,
Kept back for comparison counts randomized control touches, and Cost of
remembering combines delivered-context tokens with measured semantic-write
payload cost. Reading avoided stays Collecting or Not measured until at
least 20 treated file touches and 5 holdouts exist with a downstream join; the
dashboard does not manufacture a savings estimate from missing data.
See the cross-client capability contract and the live evaluation suite.
Every native hook writes the same bounded JSONL lifecycle record, including Claude Code's custom router and compaction paths. Records carry the client and plugin versions, event, hashed session/turn correlation, latency, outcome, input/output byte counts, and response key shape. They deliberately retain no prompt, command, tool output, file content, or raw working-directory path. The fields include OpenTelemetry log severity and resource semantics so the local files can be collected without inventing a second schema.
npm run diagnostics                         # last 24 hours, summary-first JSON
npm run diagnostics -- --hours 72 --output hook-summary.json
npm run diagnostics -- --include-events --limit 100 --output hook-report.json
Raw event rows are opt-in and capped at 1,000. The default report contains aggregate health and at most twenty recent failures/timeouts, keeping routine troubleshooting output small enough for CLI and model context windows.
The dashboard's Capture health panel shows runs, failures, timeouts and
p50/p95 latency by client. Logs rotate at 5 MiB, retain at most 40 files for 14
days, and live under .token-optimizer/logs when a state directory is set (or
~/.token-optimizer/logs otherwise). TOKEN_OPTIMIZER_LOG_DIR,
TOKEN_OPTIMIZER_LOG_MAX_BYTES, TOKEN_OPTIMIZER_LOG_MAX_FILES, and
TOKEN_OPTIMIZER_LOG_RETENTION_DAYS override those operational defaults.
An optional local proxy compresses tool results, search output, logs and
conversation history on the way to the model. A hook cannot do this: the
PostToolUse output schema is {hookEventName, additionalContext?, classifierContext?} and updatedOutput occurs nowhere in the client, so a hook
can add context but never replace a result. The proxy never tries to -- it
rewrites the outbound request, where those results already sit as history.
Two things make it different from simply compressing harder.
It never rewrites cached content. A cached prefix bills at 0.1x and a cache write at 1.25x, so compressing history can cut tokens while multiplying the bill. Measured on our own benchmark: compressing behind the cache breakpoint removes more raw tokens on every workload and costs more money on every workload. Compression stops at the frontier, and cache-weighted tokens are reported beside raw ones so the trap is visible rather than inferred.
It keeps the rows that matter. Eliding a long array after the first few rows scored 95.7% on a search payload here and destroyed both the UUID record and the error record planted in it -- the only two rows anyone would have searched for. The engine now keeps every row that departs from the shape, wherever it sits: 92.4% with the needles intact. A gate in the benchmark fails the build if a planted needle disappears, because a size metric alone cannot tell compression from truncation.
Reduction over the content each strategy is permitted to rewrite, on fixtures matching the four workloads HeadRoom publishes, is the guarded table earlier in this section -- 97.5%, 97.8%, 98.6% and 53.7% against their 72.8%, 92.1%, 92.2% and 47.4%. It is stated once and checked there rather than restated here, which is how this copy came to claim 98.9%, 98.2%, 92.8% and 61.3% long after the tree had moved.
These are not their corpora, which are unpublished; the code workloads read real files out of this repository and the rest are generated to the shape and scale of their published ones, from their own benchmark generator's definition.
Reduction is not the bill, and the two disagree. Cache changes the
arithmetic: a cached prefix is re-read at 0.1x and a rewritten one is charged at
1.25x, so an arm can remove more bytes and still cost more. Run
node bench/compression/proof.mjs and that is exactly what happens -- the
HeadRoom-style arm removes a larger share of every workload and loses on
cache-weighted effective tokens on all of them:
| workload | raw reduction, ours / theirs | effective tokens, ours / theirs |
|---|---|---|
| code search | 84.6% / 95.8% | 999 / 1,383 |
| SRE debugging | 86.2% / 97.1% | 1,833 / 2,261 |
| issue triage | 89.2% / 95.3% | 812 / 1,277 |
| grep output | 45.9% / 51.9% | 7,146 / 9,514 |
| raw build log | 54.7% / 59.4% | 14,448 / 16,769 |
| browser session | 45.7% / 49.4% | 11,398 / 14,685 |
The competitor arm is this repository's own reimplementation of their published design -- opaque hash markers, history compressed, a retrieval tool and system message injected -- not their binary. It is implemented to win where it can: the raw column is theirs on six of six.
On whole sessions. node bench/compression/session-replay.mjs replays real
recorded conversations turn by turn and prices each one the way a provider does,
charging the longest byte-identical leading run at 0.1x and everything after at
1.25x. Four independent sessions, whole request including system prompt and tool
schema, against no proxy at all:
| turns | HeadRoom's design | ours (v4-substitute) | cheaper on |
|---|---|---|---|
| 10 | 1.000x | 0.953x | 4 of 4 |
| 20 | 0.999x | 0.915x | 4 of 4 |
The replay uses stored transcripts, which discard reasoning text while retaining signatures. Its savings therefore do not establish that useful reasoning survives compression. It also uses our reimplementation of the competitor's design; these are offline estimates, not results from their shipped proxy.
Live comparison against HeadRoom's shipped proxy. The balanced four-arm run
recorded in commit f712b4ec used bench/live/ab.sh, rotated each arm through
every position, and re-ran pytest independently after each task:
| arm | mean weighted input tokens | tests passed |
|---|---|---|
| uncompressed control | 134,706 | 4/4 |
| Token Optimizer, previous 1,500-character deferral floor | 100,818 | 4/4 |
| Token Optimizer, zero floor (now the default) | 49,053 | 4/4 |
| HeadRoom shipped proxy | 48,626 | 4/4 |
Weighted input is input + 1.25 * cache_creation + 0.1 * cache_read; it excludes
output cost. Both zero-floor Token Optimizer and HeadRoom reduced that measure
by about 64% versus control. Token Optimizer used about 0.9% more than HeadRoom.
This small arithmetic repair task does not establish superiority across tasks,
compression quality, or total cost. Rotation balances run position, but does
not guarantee that shared provider-cache effects disappear.
Codex three-task comparison against HeadRoom 0.37.0 (2026-09-18). Three
synthetic controlled-read tasks, three repetitions, three arms, every arm in
every position. All 27 runs returned the correct answer, so this compares cost
at equal correctness rather than accuracy. HeadRoom ran in --mode token, its
compression-first setting, not the cache default that exists to freeze the
cache hit rate.
| arm | mean input tokens | of which cached | output | requests | agent seconds |
|---|---|---|---|---|---|
| uncompressed control | 55,632 | 43,079 | 200 | 3.0 | 19.1 |
| Token Optimizer | 42,468 | 33,052 | 189 | 3.0 | 17.3 |
HeadRoom 0.37.0, --mode token | 71,626 | 51,897 | 285 | 4.3 | 27.3 |
Input reduction against the control was 22.7% on the log task, 34.3% on the JSON task and 11.5% on the code search; against HeadRoom, 54.9%, 10.0% and 42.2%. Every task favoured this proxy on both comparisons, and the JSON column is where HeadRoom is strongest and the margin thinnest.
The mechanism is visible in two numbers that move independently. Mean input per REQUEST was 14,156 here against HeadRoom's 16,529 and the control's 18,544 -- both proxies compress, and this one compresses harder. Mean requests per RUN was 3.0, the same as the control, against HeadRoom's 4.3. A compressor that elides content the agent then has to read back spends a turn recovering it, and on these workloads a turn costs more than the elision saved; that is the failure this project's own deferral floor exists to avoid, and it is what the extra 1.3 requests are.
WHAT THIS DOES NOT SHOW. These are token counts, not dollar costs, and
bench/live/report-codex.mjs deliberately declines to price them. Three short
synthetic workloads do not establish a universal win. Each task ran in a fresh
temporary workspace with no knowledge graph, so graph injection contributed
nothing and this measures compression alone. Cached tokens are a subset of the
input column, not an additional charge. HeadRoom's compression is scored from
provider usage rather than byte counts recorded at our own listener.
Reproduce with HEADROOM_MODE=token node bench/live/codex.mjs, then
node bench/live/report-codex.mjs <evidence-dir>; the figures above were read
only after that reporter returned valid: true with balanced: true and no
failures. Four earlier campaigns were discarded rather than published: one ran
without HeadRoom's [proxy] extra so every HeadRoom run errored before
readiness, one ran HeadRoom in its cache default, one was voided by the
reporter for an incomplete request capture, and one died on ENOSPC with the
host disk full.
The subsequent Claude Code default-versus-aggressive confirmation hit Claude's weekly usage limit and is incomplete. Its missing usage cannot count as a win. Codex validation runs independently through the Responses API.
Latest Codex joint confirmation (2026-09-16). The frozen twelve-family study completed 120 pairs against installed HeadRoom 0.37.0. Our proxy passed 119/120 attempts; HeadRoom passed 120/120. One local allocation crash left unknown usage. There were 77 strict joint wins (passing, cheaper, and faster), 20 cost-only losses, 12 speed-only losses, nine losses on both measures, one equal-time pair that cost more, and the failed attempt. Across the 119 fully measured pairs only, estimated token cost was 26.9% lower and agent time 30.1% lower. JSON agent time was 5.6% higher. Only logs and refactoring met the simultaneous per-family criteria; the complete-study superiority gate failed. These results do not establish that every task is cheaper or faster. The measured build preserves explicit nulls, retains complete numeric tables, and avoids copying unchanged payloads. See the full results, every loss, and retained crash.
Earlier expanded local Codex confirmation. A preregistered seven-family study ran 70 pairs / 140 attempts against installed HeadRoom 0.37.0. Our frozen proxy passed 70/70; HeadRoom passed 69/70 with one upstream HTTP 503 and missing usage. The complete-ledger gate therefore failed: superiority was not established. Across the 69 fully measured pairs only, descriptive totals were 25.7% lower estimated cost, 38.9% lower input, and 30.0% lower agent time for our proxy. JSON remained a loss (35.1% higher estimated cost). See the protocol, all attempts, and limitations.
A subsequent rare-string-group fix targets that JSON loss. In three fully measured fresh pairs, input fell 17.7%, estimated cost 13.4%, and agent time 13.6% versus HeadRoom, with three requests each. A fourth pair had a retained upstream 503 on our arm; one measured pair still cost more. These are development results, not confirmation of the new build or an all-workload win. See the complete screen and exclusions.
Current amended Codex study. The next fixed 70-pair schedule completed: our proxy passed 69/70 and HeadRoom 70/70. Our remaining attempt hit an upstream 503 with unknown usage, so strict superiority was not established. Across the 69 fully measured pairs only, estimated cost was 27.9% lower, input 44.2% lower, and agent time 31.7% lower. Every family's mean cost favored our proxy, including JSON at 27.5% lower, but 13 individual pairs still cost more. The run includes a disclosed repair to a between-case file-hashing failure; the original product and schedule stayed fixed. See the full results, amendment, and retained failure.
Exact search rows, subsequent development. Factoring shared declaration syntax while preserving every identifier and value closed the code-size gap: 37.5% fewer bytes than archived HeadRoom on the original 40 losing inputs. Eight fresh local cases also sent fewer bytes. Four balanced live pairs all passed their audits; our estimated token cost was 50.1% lower, input 44.8% lower, and agent time 51.1% lower. This is a small development follow-up, separate from the broader study. See the captured bodies, reconstruction checks, and live evidence.
Cost-loss follow-up (2026-09-16). We investigated all 13 losing pairs and implemented exact ID-prefix factoring plus support for records inside truncated shell envelopes. A fixed follow-up of those 13 cases passed all 26 attempts; 12 pairs favored our proxy, with 33.4% lower total estimated cost. The remaining loss exposed the outer-envelope bug. After fixing it, two balanced controlled pairs both favored our proxy: all four attempts passed, estimated cost was 34.3% lower, and input was 15.9% lower. These development runs retain every original loss; cache and model variation also affect results. See the case-by-case audit, fixes, exact replay, and live evidence.
Local proxy performance (2026-09-16). Against installed HeadRoom 0.37.0, 2,160 completed local-upstream requests covered repeated and unique logs, JSON, and code-search output in three rotated arm orders. Our mean latency and process CPU were lower in all six groups. Sampled peak process-tree private memory was 80.0 MiB versus 1,909.9 MiB; this is footprint, not allocation volume. Unique code still forwarded 5.7% more bytes. HeadRoom's rate limit was disabled for this throughput measurement; compression settings stayed default. These measurements do not measure model quality or billed cost. See the raw samples, reproduction commands, and limitations.
Live Codex comparison (2026-09-15). Local Codex CLI 0.154.0, gpt-6-astra,
and installed HeadRoom 0.37.0 completed a balanced 27-run campaign. All three
arms passed all nine tasks; every initial read was complete, and all provider
ledger totals matched Codex's reported usage.
| workload | mean input, ours | mean input, HeadRoom | reduction vs HeadRoom |
|---|---|---|---|
| JSON outlier lookup | 39,318 | 44,043 | 10.7% |
| code search | 44,427 | 82,697 | 46.3% |
| log diagnosis | 39,203 | 84,308 | 53.5% |
These counts include cached input and extra retrieval turns; they are not raw compression percentages or dollar costs. Output tokens did not improve on every workload. See the Codex evidence and limitations and reproduction instructions. These three synthetic tasks do not establish superiority across all workloads.
A separate 27-run natural-workflow development screen passed all runs and measured 35.5%, 43.5%, and 16.6% less total input than installed HeadRoom for retry bug fixes, multi-file refactors, and configuration refreshes. These are small synthetic repositories with natural tool selection. Uncached input and latency have separate results; see the workflow evidence and limitations.
The proxy is enabled by default and binds loopback only.
It is now on without launching anything through us. Until 7.1.0 the only way
to be routed was to start the client through our wrapper, so anyone who installed
with /plugin and then opened Claude Code from a shortcut, an IDE or the desktop
app saved nothing -- and the doctor reported that as a broken installation rather
than as a feature that never applied. Installation now writes the endpoint into
Claude Code's own settings.json, which is the one thing a session we did not
start will read, and a small background proxy serves it. Four rules make that
safe to switch on:
token-optimizer-uninstall --apply restores it exactly, and refuses when the
value is no longer the one we wrote -- if you change it, it is yours again.Set TOKEN_OPTIMIZER_DEFAULT_ROUTING=0 to keep the wrapper-only behaviour, or
TOKEN_OPTIMIZER_PROXY_AUTOSTART=0 if you do not want a local background service
at all. Either one also undoes an entry already written.
Managed commands. Global npm installs activate Claude hooks and wrap the
client commands you actually have -- claude, codex, gemini, opencode,
qwen, crush, droid, cn (Continue), copilot and amp -- in Command
Prompt, PowerShell, Bash, and Zsh when lifecycle scripts are enabled. Only
commands already on your PATH are wrapped, so installing this does not claim a
name for a client you have not installed; TOKEN_OPTIMIZER_MANAGED_CLIENTS takes
a comma-separated list (or all) when a client lives somewhere PATH cannot see,
and 0 skips shell activation entirely. Windows installs add owned .cmd
launchers to the User PATH, so profiles and PowerShell execution-policy changes
are not required. For local installs or disabled lifecycle scripts, run
token-optimizer-install. Reopen the terminal to load the updated PATH and shell
activation. Each managed session starts its own proxy, registers the packaged
core MCP tools (including wiki), and shuts the proxy down on exit.
token-optimizer-run <client> ... works without shell activation.
Which clients can be routed, and which cannot. Ten have a supported way to redirect model traffic and are listed above. Claude Code and Gemini have exactly one provider each, so they are routed on installation. The rest choose a provider in their own configuration, and are routed once that configuration names an endpoint -- because forwarding on a guess would deliver one provider's credentials to another company. Six clients cannot be routed at all: Cursor, Cline, Windsurf, Kilo, Roo and Zed run the assistant inside the editor process and expose no documented redirect. Everything else -- the optimizer tools, the graph, the hooks -- still applies to them, and the doctor states the limitation instead of counting it as a failure.
token-optimizer-route shows what is running and what configuration has been
written on your behalf. Zed is the one client that can be routed and cannot be
routed for you -- its provider is a named entry you pick inside the editor, and
only you know which endpoint and model it should use:
token-optimizer-route                                                  # what is routed right now
token-optimizer-route zed --upstream https://api.openai.com/v1 --model gpt-4o
token-optimizer-route zed --remove
Zed's provider schema here comes from its published settings documentation and has not been exercised against an installed Zed in this repository. It is written into a file the command can take back out, and nothing is written unless the route is already being served.
Existing custom provider authentication stays in the client, and your own
endpoint stays yours: the proxy is inserted in front of whatever you configured,
never in place of it. TOKEN_OPTIMIZER_PROXY=0 disables routing and
TOKEN_OPTIMIZER_MODE=off disables optimization. npm lifecycle scripts may be
blocked, so package installation alone is not proof that activation ran.
OpenCode's session plugin uses its resolved configuration and project directory;
account credentials and provider files stay in place. Unsupported endpoints and
provider modes retain native routing. Claude routing controlled by local
managed-policy files or Windows registry policy also stays native. Remote/MDM
policy can arrive after launch; the launcher reports observed model traffic, not
just listener startup.
doctor checks routing configuration.
Request-body capture is opt-in via TOKEN_OPTIMIZER_PROXY_CAPTURE; when enabled,
it writes plaintext request content to the named directory.
Capture queues are bounded to 128 requests and 16 MiB of queued snapshots and
metadata. Excess captures are rejected with a warning while requests continue;
live audits reject incomplete capture evidence. See the
allocation hardening and follow-up results
for the reproduced OOM fix, constrained-memory replay, and remaining cost losses.
Your provider key is forwarded in the request headers and is never read, stored or written by the proxy. That is a narrower claim than "nothing sensitive is written", and the difference matters: the proxy does write message content to disk, described next, and it does not inspect that content for secrets. If a secret is in your conversation, it can reach a spill file the same way any other text does.
It will not reach an unencrypted network, though: an upstream that is neither
https nor loopback is refused rather than forwarded to, and with no upstream
configured the proxy serves only Anthropic's own routes -- so a client for a
different provider is told to name its provider rather than having its key sent
to the wrong company.
It does write some payload to disk, and you should know exactly when. An elision has to name a way back to what it removed, and content that arrived in a tool result has no file of its own -- so that content is written to a spill file and the marker names its path. This happens only when an engine actually elides something recoverable-by-path: a JSON array tail, a set of function bodies, a passage of prose. Requests below the size floor, requests nothing claims, and every elision that is lossless are all written nowhere.
Spills go under your OS temp directory in token-optimizer-spill/, one file per
distinct content, created 0600 (owner read/write only) and named by an HMAC of
the content under a salt generated fresh in each proxy process -- so the name
discloses nothing and two runs do not collide. They are never read back by us;
the agent reads them with the Read tool it already has, which is the whole
point of a path instead of a hash.
They are not deleted while the proxy is running, and that is deliberate: a marker whose spill has been swept is exactly the dangling reference this design exists to avoid, and the agent may follow a path many turns after it was written. So retention within one run is bounded only by the distinct content you elide -- there is no quota, and a very long session that elides constantly can accumulate.
When the proxy stops, its spill directory is removed. Each proxy process gets
its own directory under token-optimizer-spill/, so stopping one never sweeps
another's live paths, and the moment it stops is also the moment no agent can
still be following one of them. If a run ends without that cleanup -- a kill
signal, a power cut -- the directory is left behind in your OS temp directory
and is safe to delete by hand. Running with the proxy off writes no spills at
all.
| variable | default | what it does |
|---|---|---|
TOKEN_OPTIMIZER_PROXY | on | the compression proxy itself; set 0 to opt out |
TOKEN_OPTIMIZER_COMPRESSION | balanced | balanced, aggressive, conservative, lossless |
TOKEN_OPTIMIZER_PROXY_KNOWLEDGE | on | put what this project already learned in the cached prefix |
TOKEN_OPTIMIZER_PROXY_NET_SAVING | off | never send upstream more bytes than the client gave |
Both of the on rows said off here until 7.1.0, which was wrong about the
shipped code rather than a change of default: an unset value has always meant
enabled, and 0, false, no and off are what turn either one off.
TOKEN_OPTIMIZER_PROXY_NET_SAVING is off because the knowledge block is supposed
to grow the request: it is charged once as a cache write and then read at 0.1x for
the rest of the session, which pays on a long conversation and does not on a short
one. Turn it on and the block is dropped on any turn where sending it would hand
upstream more bytes than the client handed us -- the wire never inflates, and the
prefix knowledge is what you give up for that.
Each switch above is its own decision, which is fine until there are ten of them.
A channel is one decision instead: stable is what is on by default today, and
each wider channel carries everything the narrower ones do plus the features still
being measured.
| variable | default | what it does |
|---|---|---|
TOKEN_OPTIMIZER_ROLLOUT_CHANNEL | stable | stable, beta, canary, dev |
TOKEN_OPTIMIZER_FEATURES | unset | a comma list of feature names to turn on within the channel |
TOKEN_OPTIMIZER_DISABLE_FEATURES | unset | a comma list to turn off, whatever else is set |
beta turns on install self-repair; canary adds compact tool definitions. Those
two are staged: the channel is what enables them.
Everything else a wider channel reaches is request-only, and a channel never turns
one on for you -- it only lets you ask. beta makes the output shaper and the
shared knowledge graph askable, canary adds identifier substitution and
thinking-block dropping, and dev holds nothing back. Each of those either changes
what the model writes or forces an answer the code otherwise works out from the
directory it is running in, which is a decision worth naming rather than inheriting:
TOKEN_OPTIMIZER_ROLLOUT_CHANNEL=canary TOKEN_OPTIMIZER_FEATURES=substitution
A variable you already set still wins over the channel. If
TOKEN_OPTIMIZER_PROXY_SUBSTITUTE=1 is in your settings, substitution is on even
on stable, because that switch shipped before channels existed and moving you to
a channel is not supposed to quietly turn your own configuration off.
TOKEN_OPTIMIZER_DISABLE_FEATURES is the one thing nothing overrides.
A name this does not recognise turns nothing on, and a value it cannot read is not treated as yes. Both are reported rather than guessed at:
npm run doctor           # the channel and what it turned on
npm run doctor -- --features   # every feature and the reason for each
| variable | default | what it does |
|---|---|---|
TOKEN_OPTIMIZER_TELEMETRY | off | aggregate counts into a file in your home directory |
TOKEN_OPTIMIZER_BEACON | off | upload that file; requires the one above as well |
DO_NOT_TRACK | unset | overrides both, whatever else is set |
TOKEN_OPTIMIZER_BEACON_URL | project | send somewhere else, for a fork or a self-hosted table |
TOKEN_OPTIMIZER_BEACON_KEY | packed | the key to send with; empty in a build without one |
TOKEN_OPTIMIZER_BEACON_TABLE | telemetry_events | the table to insert into |
TOKEN_OPTIMIZER_UPDATE_CHECK | on | ask npm for the latest version, in doctor only |
The key is not in this repository. It is public and the package is published, so
a committed key would be handed to everyone who runs npm view and could not be
rotated out of the copies already installed; the release workflow stamps it into
the tarball instead. A build without it still works and still aggregates locally
-- it just cannot upload, and install_doctor prints packed without a key
rather than letting an opt-in look like it is working.
lossless is worth knowing about: it forbids every transform that removes
something the output cannot reconstruct -- function bodies, array tails,
lower-signal prose -- and keeps the ones that can, which is whitespace, null
keys, folded duplicate lines with their timestamps listed, repeated path
prefixes, and back-references to content still in the request. Measured on the
codebase-exploration workload it still removes 12.2%, with zero lossy
elisions. For review or audit work where "the model can read the path" is not
an acceptable answer, that is the setting.
Presets are a starting point, not a ceiling: the library takes a
CompressionOptions object layered over the preset, so "aggressive, but keep
six head rows" is expressible.
The expensive failure here is turns, not tokens. This project measured a posture that cut nothing and cost 1.471x through extra turns alone. So a finding that prevents one wasted turn pays for a great deal of context.
The knowledge graph knows things that would prevent them, but until now it
reached the model two ways and both arrive too late or too dear: a SessionStart
index chosen once from the opening task text, and a PreToolUse advisory that
fires after the model already decided to make the call it is advising about --
so acting on it costs the very turn it was meant to save.
Verified project findings enter the cached prefix by default, with a
2,000-character budget. The proxy freezes the selected block for a conversation
to preserve the cache; new sessions can select newly recorded findings. This
includes the Codex Responses API path. Shared graphs exclude project-specific
claims. Set TOKEN_OPTIMIZER_PROXY_KNOWLEDGE=0 to disable injection.
Added knowledge is reported separately as injectedChars. It adds input tokens;
net cost improvement requires measuring whether it prevents enough work.
Earlier head-to-head results do not establish that the newly enabled combination
wins every workload.
An image block was invisible to all of this until recently -- every walker keyed
on block.text. That matters because an image costs about width * height / 750 tokens, so one 1456x816 screenshot is roughly 1,585, re-sent as history on
every later turn. A browser-driving agent sends the same frame repeatedly, and
those repeats now collapse to a reference to the copy already in the request.
Dimensions come from the file header, so there is no codec dependency; resizing
is deliberately not done for the same reason.
Retention is ranked by BM25, which is why this needs no Python, no model weights and no RAM floor, and why it is deterministic enough to keep a cached prefix byte-stable. Lexical has a ceiling, though: "the database ran out of handles" shares no token with "connection pool exhausted", and worse, BM25 does not go quiet on that question -- it confidently picks the wrong line.
So there are two ways to do better. registerRanker installs any synchronous
ranker. Or supply a SemanticEncoder and let the proxy warm an embedding
cache: a request-level async pre-pass embeds the candidate units in one batch,
and the engines then read vectors synchronously, exactly as before. An
onnxruntime-node adapter is included, loaded dynamically so the runtime is
never a dependency of this package.
Anything the pre-pass did not see falls back to BM25 rather than scoring zero -- a missing vector is our omission, not evidence about the line.
The adapter is verified against real inference, not mocked:
npm run verify:onnx runs nine checks against a 2.3 KB ONNX graph with real
weights, committed alongside the generator that builds it. It is a script
rather than a jest test because onnxruntime checks instanceof Float32Array
in native code and jest's per-suite VM realm has its own typed arrays; CI
installs the optional runtime and runs it.
Not claimed: that an embedding model actually beats BM25 on these workloads. The mechanism is proved and the measurement is not done.
Everyone else checkpoints and restores what you had — which spends the scarcest budget in the session replaying context you already paid for.
Selection here is derived, not a category list: cost-to-rederive × irrecoverability × reuse-probability, with dead ends and decisions on a floor,
because cheap-to-find is not the same as cheap-to-find-again. Restoration then
adapts to the situation — mid-problem, cold resume, or in-flow — within a
measured budget:
Where you were: does clock skew explain the 401s? ruled out: token signing, clock drift on the client untested: NTP skew on the server
That is resuming a thought. A summary describes one.
A large tool result becomes a preview chosen by the session's actual question, after parsing the output's shape (test report, diff, stack trace, log, JSON) — not the first 40 lines because they are first.
[selected against: "which shard fails?"]
--- failures ---
  FAILED  DBNetTests.BceOnRelu -- expected 0.0 got NaN
  FAILED  TftGradientFlow -- gradient did not reach the encoder
---- omitted: 1,760 lines of passing tests (expand 8bb6bd66) ----
Every cut is named, because a model reasoning over a silent truncation
cannot know it is missing anything. expand serves from a content-addressed
store — it never re-runs your test suite — and expanding both teaches the next
preview and promotes what you needed into the graph, so the second expansion
never happens.
Provider caches are billable and provider-specific; a cache hit is not a free input token. For example, Anthropic publishes separate cache-read and cache-write multipliers, while OpenAI and Gemini expose their own cached-input usage and pricing rules. Token Optimizer reads native cache fields when the client supplies them and keeps reads, writes, uncached input, and output separate. It never applies one provider's cache multiplier to another client. The attribution view then does the part a hit rate cannot:
! CLAUDE.md:2 has an embedded timestamp, invalidating everything after it
    about 329,421 tokens re-written per session
Attributed to a line, priced by what sits behind it. Keep-warm is decided by expected value from your observed gaps, per TTL tier — and when neither tier pays, it says so.
Everyone guesses from task shape and never checks. This reads which model ran each episode and what happened — retries, errors, turns — and prices both mistakes: what an overpowered model wastes, and what an underpowered one costs in retries. A tier that needs a retry in more than half its episodes is excluded at any price, because four cheap turns that fail are not cheap.
A report is read once and forgotten. Here a detection produces a durable, measured, reversible fix — a skip rule, a composite touch — plus a ~50-token session-start briefing so the waste never starts. Detectors are a shipped floor plus patterns derived from your project's own history, each carrying what it has actually saved:
generated/schema.d.ts: read in 9/9 sessions, never the source of a finding
    3,400 tokens/session; cost equivalent not priced; apply: waste_audit action="apply"
Anything that touches your files is proposed as a diff and never applied.
fleet_audit ranks your whole machine by measured cost, and does something a
per-project scanner cannot: a fix proven in one project is offered to the others
containing the same file contents, carrying the evidence from where it was
measured. Matching is by content hash, never by filename.
It also runs the natural experiment nobody else can — enforcing clients versus directive ones — and reports it whichever way it falls, with the confound stated.
Every failed tool call you have already paid for is sitting in your agent's own
transcripts. npx token-optimizer-learn reads them locally, groups the failures
that keep repeating, and writes the ones worth remembering into the instructions
file that agent already reads -- CLAUDE.md for Claude Code, AGENTS.md for
Codex.
npx token-optimizer-learn                  # what it found, printed, nothing written
npx token-optimizer-learn --projects       # which projects have transcripts
npx token-optimizer-learn --since 14 --write
--agent <claude|codex|auto>, --project <path>, --since <days>,
--max-sessions <n>, --json. Nothing is written without --write, and a
block it writes is delimited, so running it again replaces its own advice instead
of appending another copy -- nothing outside those markers is ever touched.
Three things it refuses to do, because each one produced a confidently wrong rule on a real corpus:
cd X && git grep a && ls b failed, so those are
counted as unattributable and reported as a number rather than pinned on the
first command.It reads local files only -- no network, no upload -- and reduces your home
directory to ~ before any recommendation text is written. TOKEN_OPTIMIZER_LEARN_PLUGINS
takes a comma-separated list of module specifiers to add another agent's format;
nothing is discovered or imported unless you name it.
That is a bigger ask than a normal dependency makes, so:
Verify the release. Published from CI with npm provenance — npm audit signatures ties the artifact to the workflow run and the commit, without
trusting us. CHECKSUMS.sha256 ships alongside for offline checking.
If nothing seems to be happening, the lifecycle bundle is probably not
installed. An MCP server process cannot modify the host that launched it, and
npm 11 gates lifecycle scripts behind allow-scripts. Install the native
plugin/hook bundle listed for your client below; adding only the MCP server gives
the model tools but no pre-execution veto. For a legacy global Claude Code
installation, recovery is one line:
npx token-optimizer-install     # wire Claude Code hooks
npx token-optimizer-doctor      # prove the Claude hooks work
Check that it works — not that files exist.
npx token-optimizer-doctor # or npm run doctor, from a clone
It feeds a synthetic payload to the real hook binary and asserts a large read
is refused and a small one is not. A checklist would have passed on the exact
bug this project once shipped, where the plugin was connected, visible in
/mcp, and saving nothing. Every failure names its own fix.
Every refusal carries its own off switch. Enforcement that hides its disable is coercive, and the person who needs it is mid-refusal, not reading a README:
auth.ts is 91 KB. Call smart_read instead.
(Not what you wanted? TOKEN_OPTIMIZER_MODE=off disables enforcement.)
Removal is exact. The installer records every file it wrote, with hashes.
Uninstall removes only what still matches; anything you edited since is left in
place and named. Your own hooks are never touched, and we never rewrite your
settings.json — we merge into it.
npm run uninstall-hooks              # show the plan; changes nothing
npm run uninstall-hooks -- --apply   # carry it out
Every tool in this space reports "tokens saved" computed from its own assumptions. That number cannot be wrong, because nothing checks it.
For optimizer results, this records the materialized before-state and the text actually returned to the client, then subtracts any linked expansion responses. Native graph-substitution counterfactuals stay labeled as modeled and outside the main headline.
The graph's broader claim—whether delivered knowledge prevented later re-reading—is causal, so it runs a randomized holdout. Delivery is silently withheld on a slice of file touches, stratified by file, and the effect is the difference in downstream reads between arms. That effect is not added to the combined net until the experiment can support it, and the page will tell you plainly:
the graph is NOT yet paying for itself
A tool that can only ever report good news is not reporting. The same discipline
runs throughout: an unmeasurable saving renders as unknown, never as zero,
and never as $0.00 — because "cannot tell yet" printed as "saved nothing" is a
silent false negative, and dollars get quoted to other people.
The tier is a protocol guarantee, not a preference:
The exact surfaces still differ. For example, a protocol that can replace a large read before it reaches the model provides a stronger token guarantee than one that can only observe it. The generated registry, adapters, dashboard, and certification report all read the same capability source so those claims cannot drift independently.
Every config shape is confirmed against that client's published documentation, with the source URL recorded in its README.
npm run verify:all
| Suite | Checks | What it proves |
|---|---|---|
test | 2,437 | Enforcement, staleness, injection, consolidation, disclosure, cache, routing, trust — driving the real hooks over stdin |
verify:clients | 253 | Every client config, lifecycle manifest, and enforcement surface matches its documented schema |
verify:harvest | 26 | Request shape, response parsing, and that no secret from a tool result crosses the wire |
verify:ui | 22 | Real headless Chromium: layout, label collisions, legibility |
doctor | 10 | The installed hooks actually refuse, and the server actually answers |
These are not decoration. They found six client configs that would have failed silently, an installer that destroyed user hooks, a Windows path bug that made enforcement blind to half its own refusals, and an uninstaller that printed a plan and deleted nothing.
OrcaRouter is an OpenAI-compatible AI gateway that routes many providers behind one endpoint. It is wired here as a first-class provider for the optimizer's own model calls, with two independent ways in:
| Choice | Provider id | What it does |
|---|---|---|
OrcaRouter - API | orcarouter | You paste an sk-orca-… key you already hold. Nothing opens. |
OrcaRouter - Auth | orcarouter-oauth | OAuth 2.0 + PKCE: a browser asks for consent and issues you a key. |
Both produce the same ordinary OrcaRouter API key, and everything downstream —
the Bearer header, the endpoint, model discovery, 401 recovery — is identical
whichever one you used. The two are not interchangeable in the UI on purpose: a
single button that sometimes asks for a key and sometimes opens a browser makes
logout, reauthentication and support harder.
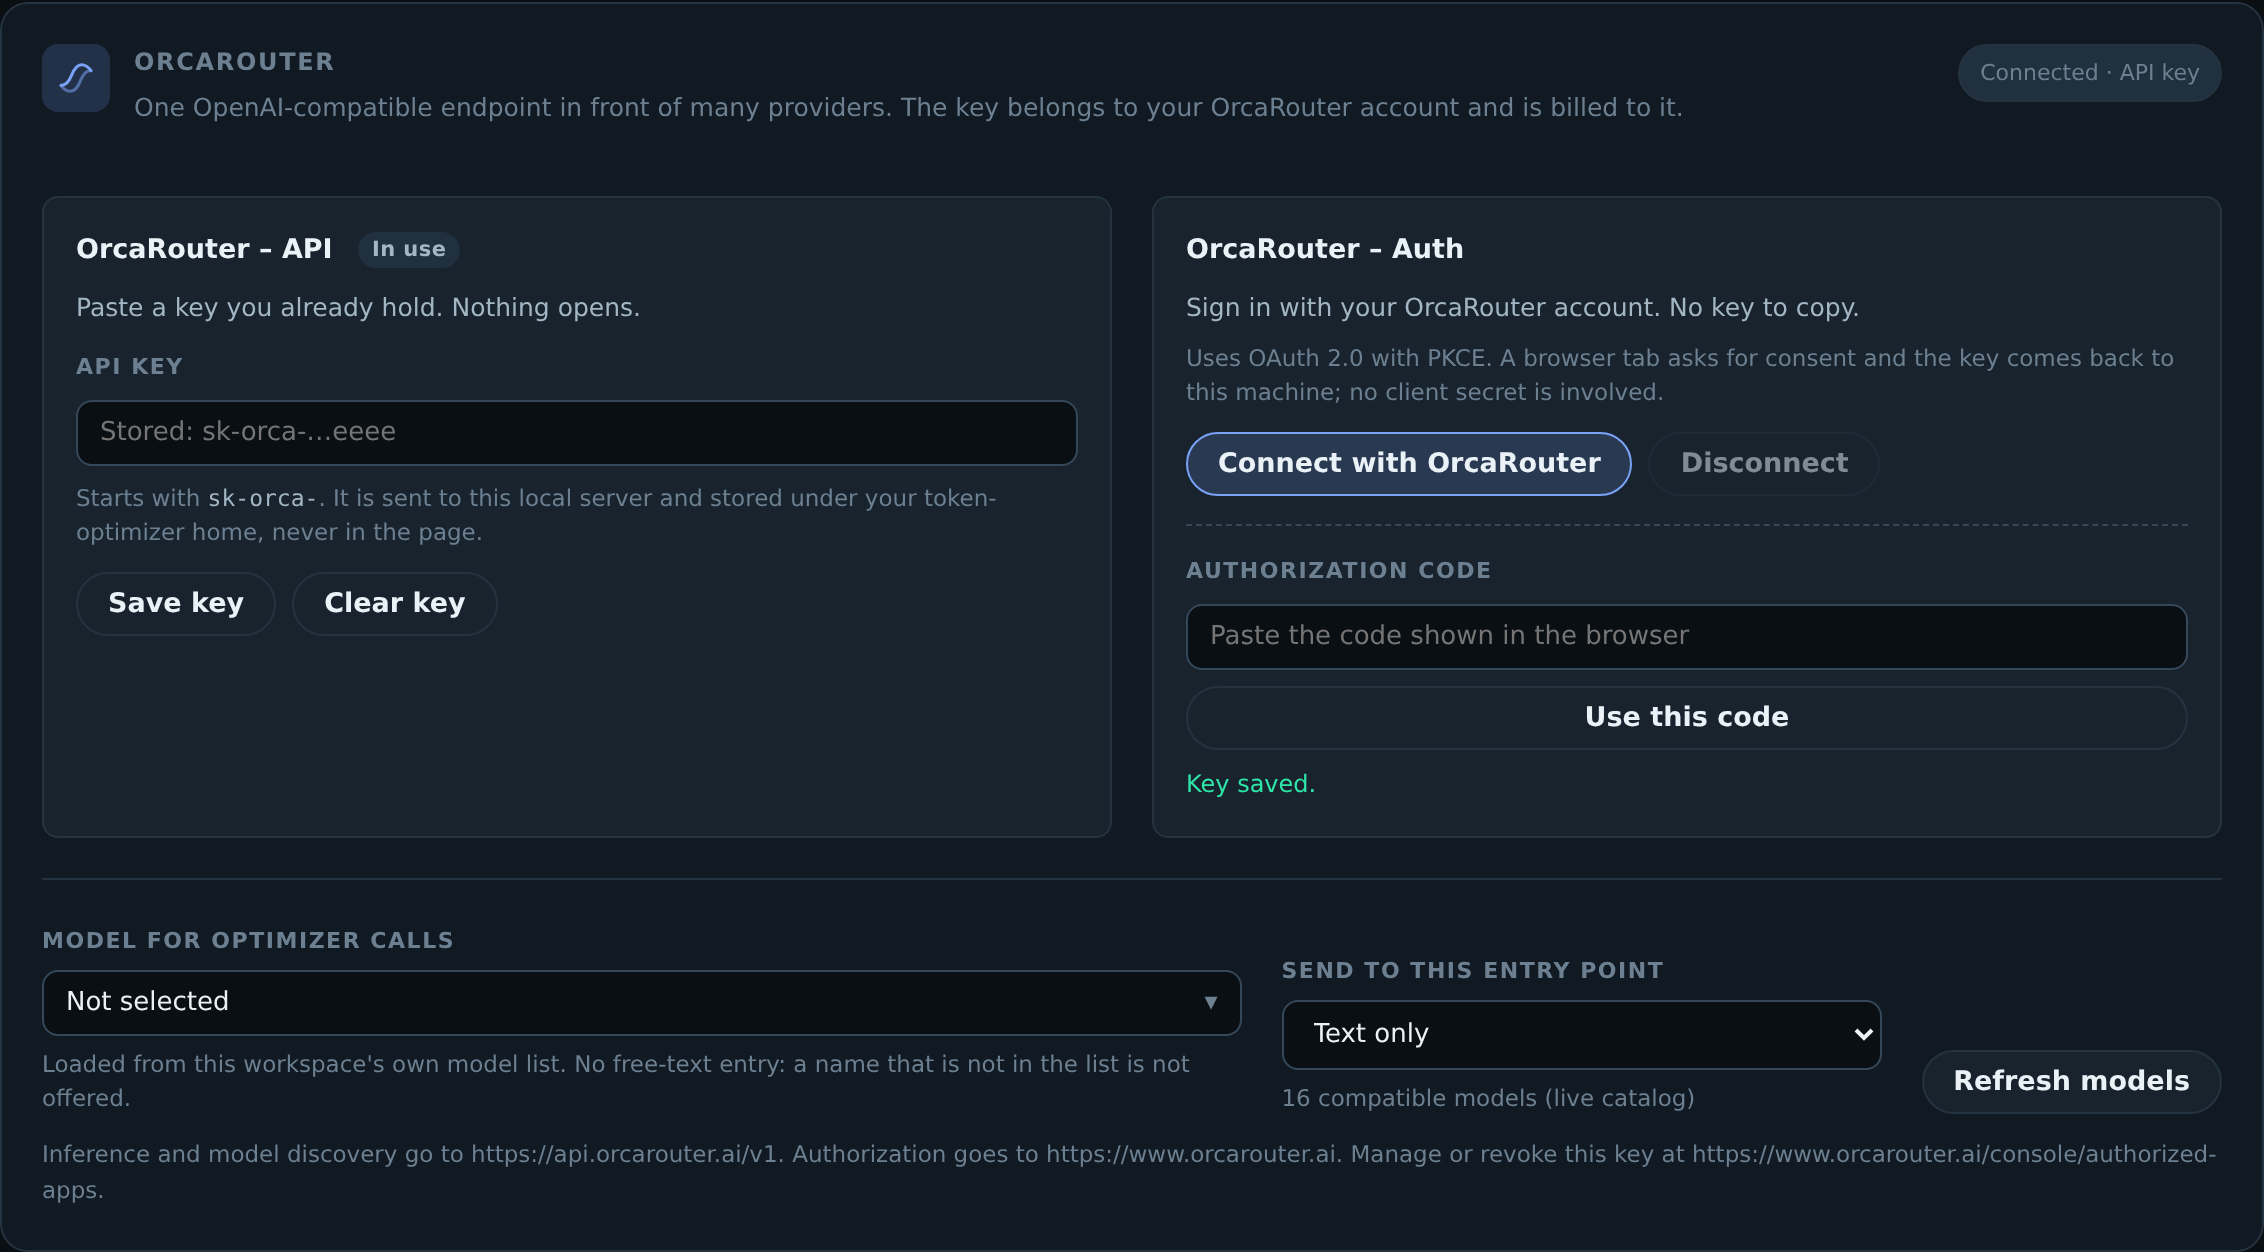
Open the dashboard (npm run dashboard) and use the OrcaRouter card, or set
it from the environment:
export ORCAROUTER_API_KEY=sk-orca-…          # the API-key choice
export TOKEN_OPTIMIZER_ORCA_MODEL=orcarouter/auto   # which model the optimizer calls
Or connect with an account instead, which writes the issued key under
$TOKEN_OPTIMIZER_HOME (default ~/.token-optimizer) with owner-only
permissions:
token-optimizer-route orcarouter --connect   # opens a browser, then stores the key
token-optimizer-route orcarouter --status    # shows a redacted status and the origins in use
token-optimizer-route orcarouter --clear     # removes the stored key
A PKCE-issued key is durable, not a refresh token. OrcaRouter returns a
long-lived key, not an access/refresh pair, so it is reused until you revoke it
at https://www.orcarouter.ai/console/authorized-apps — there is no refresh to
schedule and re-authorizing on every launch would hit the account's limit of ten
keys per 24 hours. When the relay answers 401, the exact account and credential
generation that made the rejected request is marked for reauthentication, and
nothing attempts a refresh. Refreshable OAuth tokens rotate automatically;
durable key grants such as OrcaRouter are reused until the provider revokes them.
Authentication and inference are different hosts, and neither is derived from the other:
| Purpose | Default |
|---|---|
| Consent screen and code exchange | https://www.orcarouter.ai |
| Inference and model discovery | https://api.orcarouter.ai/v1 |
https://api.orcarouter.ai/v1/auth/keys is a 404 — the auth endpoints are not
under the relay. Self-hosted installs can set ORCA_BASE_URL for a single shared
origin, or ORCA_AUTH_BASE_URL / ORCA_API_BASE_URL separately; explicit values
win, and cleartext HTTP is permitted only for loopback.
The model control is a listbox built from GET /v1/models on the configured
origin, using your own key so the list is what your workspace can actually call.
Model ids keep their vendor/model namespace. Options are filtered per entry
point, and a model that does not declare a capability is not offered rather
than offered and then rejected:
?capability=chat, and the model must declare an openai,
anthropic, gemini or openai-response endpoint type;architecture.input_modalities entry
for the modality being sent (an undeclared capability fails closed);embeddings, image-generation, openai-video and jina-rerank endpoint
types.If discovery fails, a small verified fallback list is shown and labelled as
such (openai/gpt-5.5, anthropic/claude-opus-4.8, google/gemini-3.5-flash,
deepseek/deepseek-v4-pro, orcarouter/auto), with its context, modality and
reasoning-effort metadata intact. A successful live result is authoritative and
never has the fallback mixed into it.
| Text entry point | After switching to images |
|---|---|
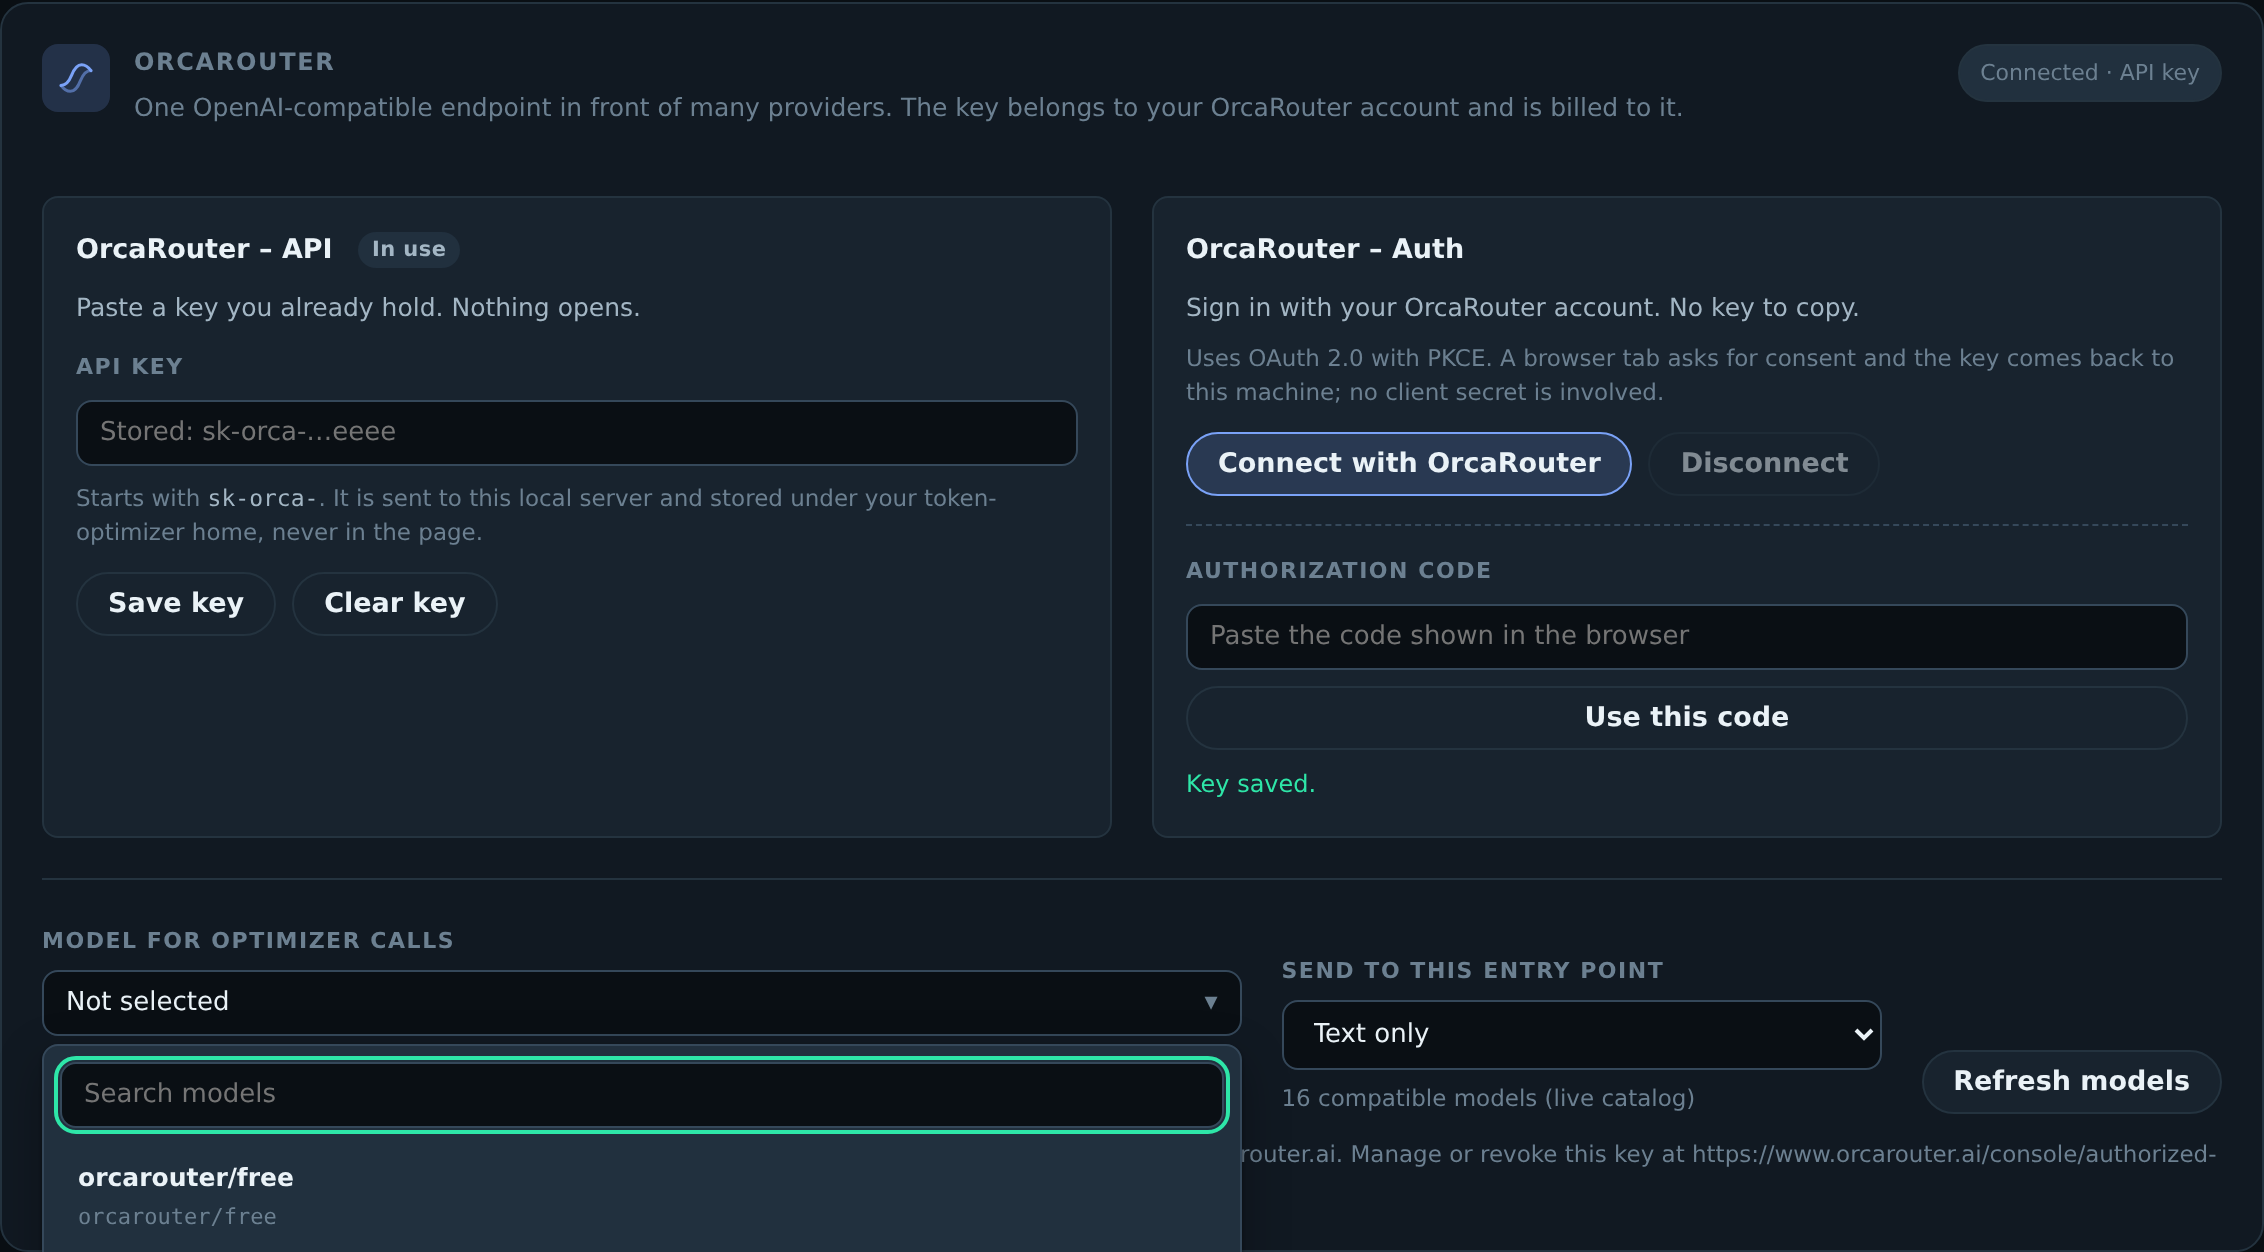 | 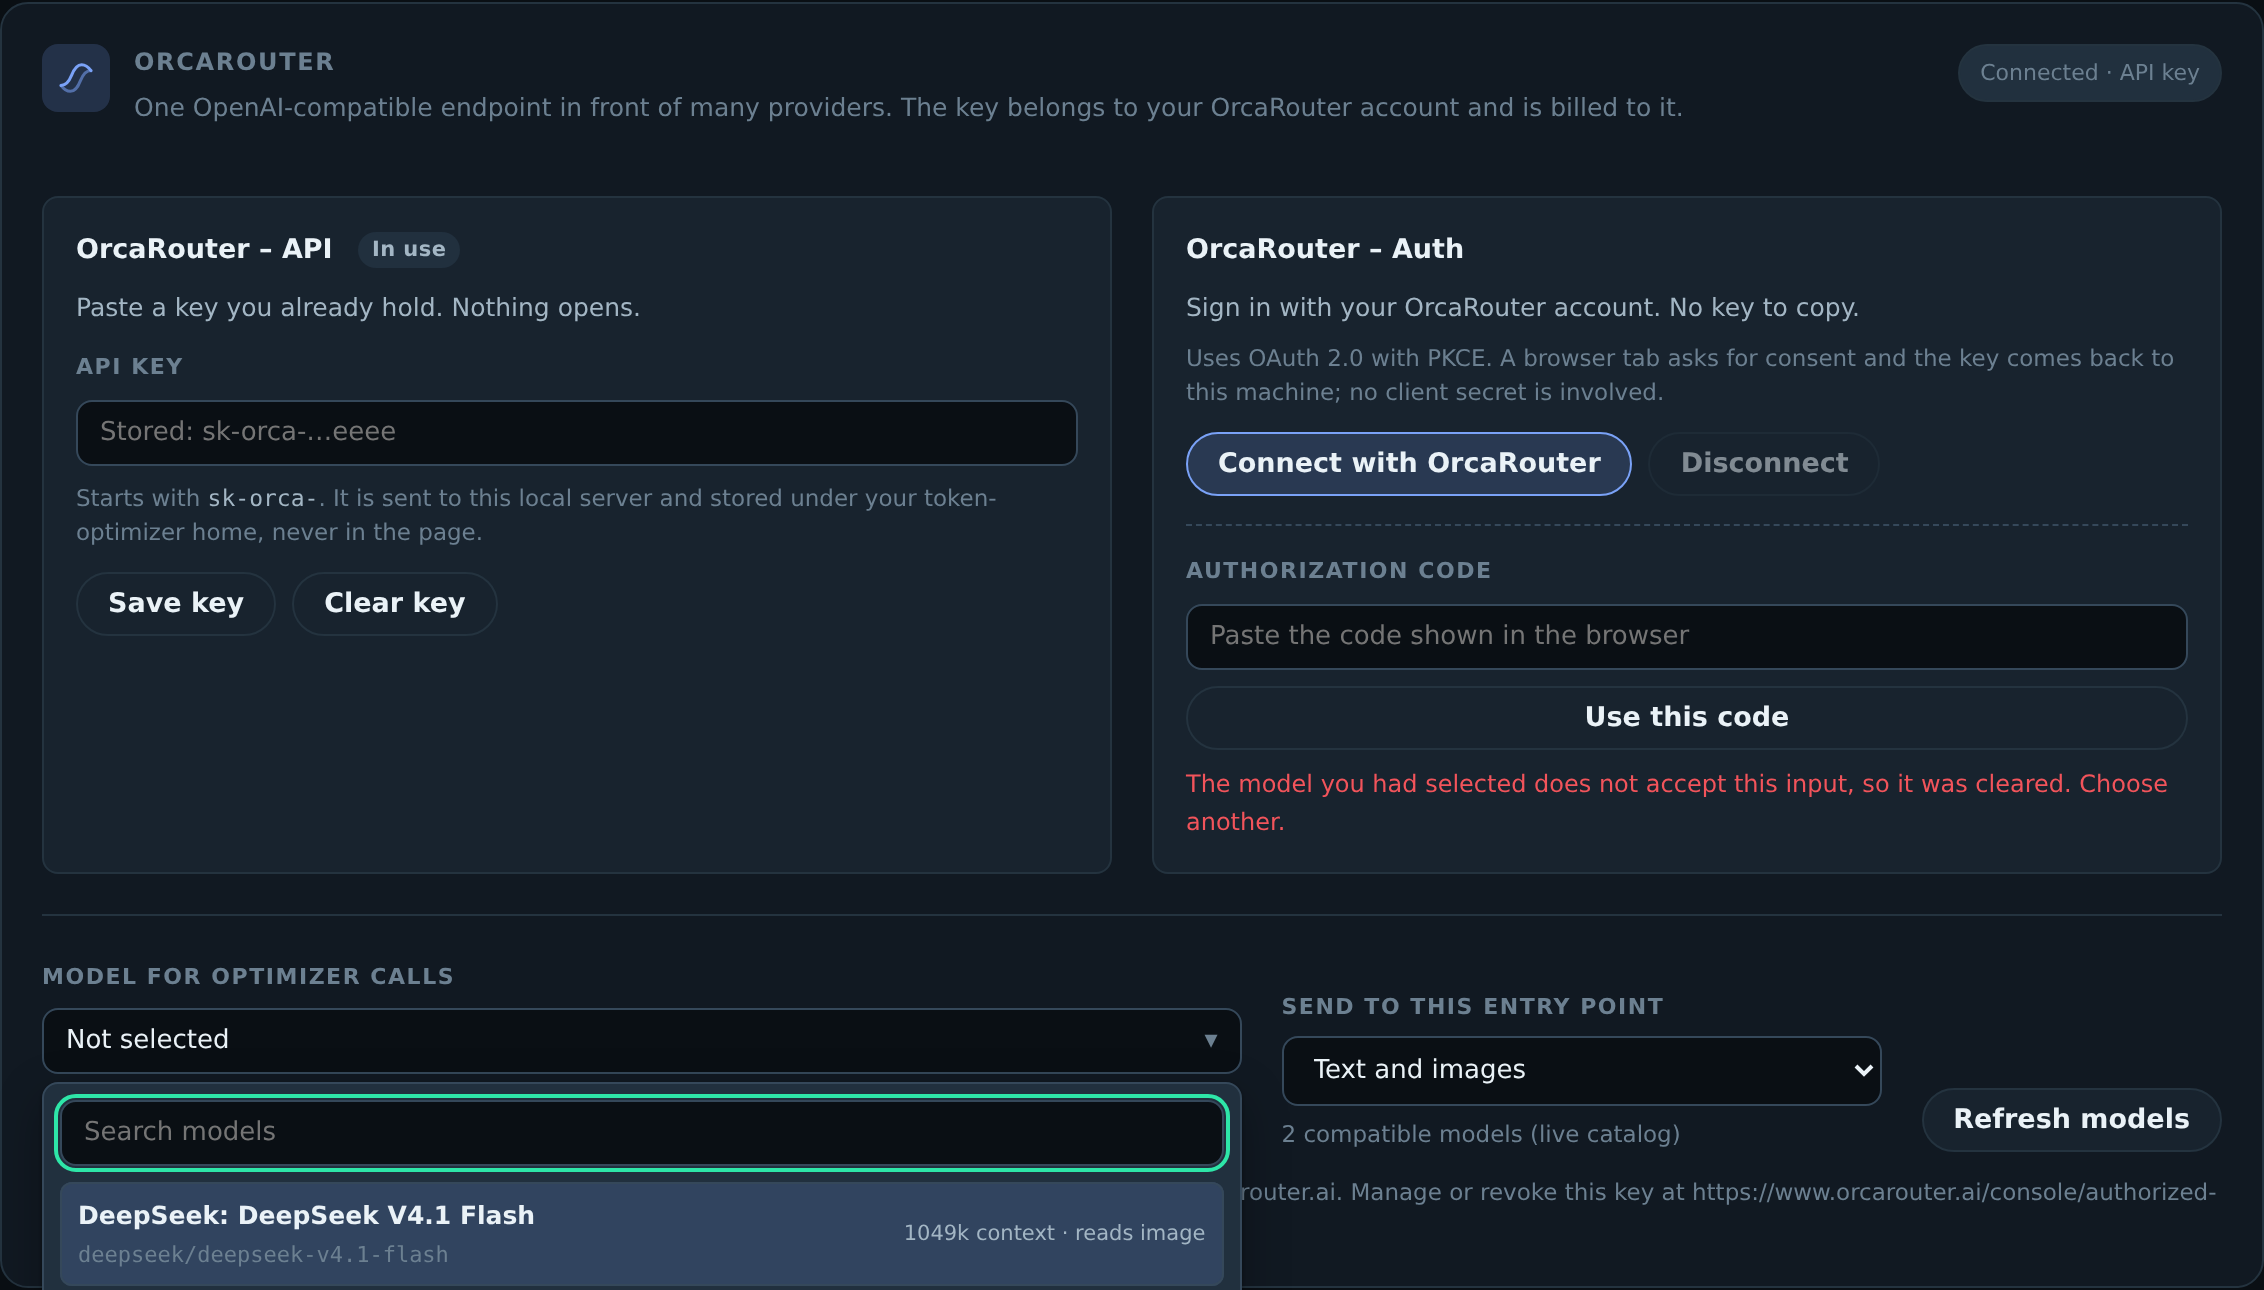 |
The second capture is after the entry point is switched to images: the text-only selection is cleared, and only models whose catalog entry declares image input remain.
npm run evidence:orcarouter regenerates the screenshots and assertions for the
card into orca-evidence/ (untracked — it is a run artifact). The copies linked
from this README live in docs/media/orcarouter/, alongside the other dashboard
captures. A delivery check reads orca-evidence/ and refuses a patch that ships
it, so the directory is ignored rather than committed.
| Token Optimizer | Typical alternatives | |
|---|---|---|
| License | MIT — commercial use fine | Often noncommercial-only; check before using at work |
| Default behaviour | Refuses the wasteful call | Suggests a better tool |
| Re-read of an unchanged file | Returns a diff | Returns the file again |
| Savings figure | Direct before/return ledger; causal graph effect separately held out | Computed from the tool's own assumptions |
| Cross-session memory | Findings, decisions, dead ends | Usually none |
| Compaction | Consolidation, ranked by cost-to-rederive | Checkpoint and replay |
| Cache economics | Measured from the transcript, attributed to a line | Rarely addressed |
| Model routing | Measured from episode outcomes | Guessed from task size |
| Cross-project | Fixes transfer by content hash | Per-project only |
| Clients | 16 | 3–6 typical |
| Telemetry | None | Varies |
Every client launches the same stdio server — npx -y @ooples/token-optimizer-mcp@latest —
but they differ in what they let a hook do, and that difference is the whole
product. A client with a pre-execution veto can have the wasteful call refused;
one without can only be told. Both are listed honestly below.
Ready-made configuration for all sixteen lives in
integrations/, generated from one source and validated by
npm run verify:clients. Full matrix: docs/CLIENT_SUPPORT.md.
Every MCP connection also receives capability-aware mandatory routing
instructions in its initialize response. That gives all clients a universal
always-on policy, but only the ten clients with native pre-tool surfaces can
hard-veto a wasteful built-in call; install their lifecycle bundle for actual
enforcement.
These ten clients expose a pre-execution hook. Their packaged lifecycle bundle
shares one capability-aware decision engine and defaults to assist: routing,
retrieval, capture and harvest all on, no refusals. Set
TOKEN_OPTIMIZER_MODE=enforce if you want expensive built-in calls vetoed, or
off to disable the hooks entirely.
| Client | Installable lifecycle surface |
|---|---|
| Claude Code | Native plugin: /plugin marketplace add ooples/token-optimizer-mcp, then /plugin install token-optimizer@token-optimizer |
| Codex | Native plugin in integrations/codex/plugin, or standalone hooks in integrations/codex |
| GitHub Copilot CLI | Project hooks in integrations/copilot |
| Gemini CLI | Gemini extension at the repository root, backed by integrations/gemini |
| Qwen Code | Extension bundle in integrations/qwen |
| Cursor | Project hooks and always-applied rule in integrations/cursor |
| Cline | Project hooks and rule in integrations/cline |
| OpenCode | In-process plugin and hooks in integrations/opencode |
| Kilo | In-process plugin and hooks in integrations/kilo |
| Windsurf | Project hooks and rule in integrations/windsurf |
Roo Code, Zed, Amp, Continue, Crush, and Droid do not expose a packaged pre-execution bridge that can safely veto built-in calls. Their generated, always-on rules make optimized routing mandatory whenever the exact MCP schema is visible, and fail open to a bounded native operation when it is not. The integration directories contain both the MCP config and the rules file at the paths documented by each host.
These paths are checked, not assumed. Verifying them against each client's published docs found six configs that would have installed cleanly and never loaded — including Kilo, whose schema shares nothing with the
mcpServersconvention the other clients use. A convention is not a schema.
For the best experience, install the Codex plugin. It bundles the MCP server, the token-optimization skill, session guidance, and a large-read hook:
codex plugin marketplace add ooples/token-optimizer-mcp
codex plugin add token-optimizer@token-optimizer
Review and trust the bundled hooks with /hooks, then start a new conversation. If you prefer an MCP-only installation, use:
codex mcp add token-optimizer -- npx -y @ooples/token-optimizer-mcp@latest
On Windows, if PowerShell blocks the codex.ps1 shim, use the command launcher directly:
codex.cmd mcp add token-optimizer -- npx -y @ooples/token-optimizer-mcp@latest
This writes the server to ~/.codex/config.toml. Codex CLI, the Codex IDE extension, and the Codex app on the same host share that configuration.
codex mcp get token-optimizer
codex mcp list
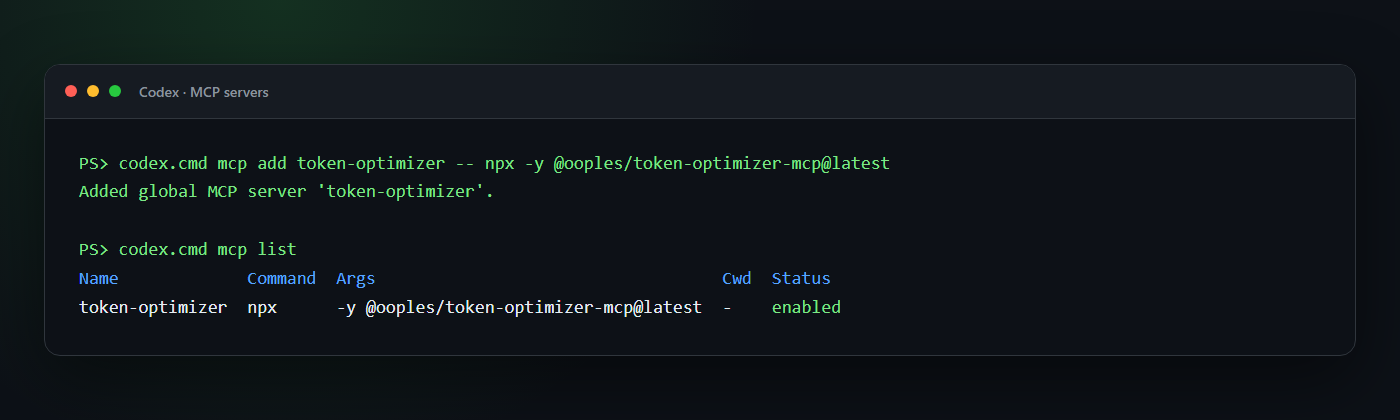
Start a new Codex conversation after installation so the new tools are discovered. In an interactive CLI session, /mcp shows the tools available to the conversation.
The plugin supplies both automatically. For an MCP-only installation, add the guidance from integrations/AGENTS.md to a project or global AGENTS.md. A ready-made standalone hook is also available under integrations/codex/hooks; merge its hooks.json into ~/.codex/hooks.json, copy the script to ~/.codex/hooks/, and review it once with /hooks.
The Codex hook injects guidance at SessionStart. Under TOKEN_OPTIMIZER_MODE=enforce it blocks expensive native operations when the bundled MCP has an exact replacement, including a single unambiguous code-mode shell call such as cat or Get-Content; multi-operation orchestration remains advisory so unrelated work is not discarded, and a second attempt at the same target passes through if the MCP is unavailable. The default is assist, which keeps retrieval and capture but never vetoes; TOKEN_OPTIMIZER_MODE=advise adds the routing advisory without vetoes, and off disables the hooks. The AGENTS.md/skill guidance remains important.
If you prefer a smaller instruction block:
## Token optimization

Use the token-optimizer MCP for large or repeated reads:

- `smart_read` for files over roughly 400 lines and for files already read once.
- `smart_glob`/`smart_grep` for large search results.
- `optimize_text` to store bulky text outside the model context.
- `get_optimization_report` when the user asks for token or compression stats.

Use normal tools for small, one-off operations.
See the current Codex hooks documentation for hook trust, matching, and tool-coverage details.
If you prefer to edit ~/.codex/config.toml yourself:
[mcp_servers.token-optimizer]
command = "npx"
args = ["-y", "@ooples/token-optimizer-mcp@latest"]

# Optional: keep the cache in a custom location.
# env = { TOKEN_OPTIMIZER_CACHE_DIR = "/absolute/path/to/cache" }
Install the plugin, not the bare MCP server. The plugin is the only path that optimizes by default; adding the MCP server alone gives the model a set of tools it is free to never call.
/plugin marketplace add ooples/token-optimizer-mcp
/plugin install token-optimizer@token-optimizer
/reload-plugins
That is the whole installation. There is nothing to configure and no flag to turn on.
From the first message of the next session, expensive built-in calls are refused and redirected to the optimized equivalent:
| You (or the model) do this | What happens |
|---|---|
Read a file over ~25 KB | Denied → smart_read (cached) |
Read any file already read this session | Denied → smart_read (returns only the diff) |
Grep file contents / Glob for files | Denied → smart_grep / smart_glob |
Edit a file over ~25 KB | Denied → smart_edit (returns a diff, not the file) |
cat/head/tail/Get-Content a large file | Denied → smart_read |
grep -r / rg across the tree | Denied → smart_grep |
| Context fills and compaction starts | optimize_session runs first |
The re-read case is usually the largest single win and the one most often missed: a 5 KB config read fifteen times across a session costs far more than one 200 KB file read once. Size-based rules never catch it.
Three properties, all tested:
git log | head,
and binary paths are never touched.One variable, no reinstall:
TOKEN_OPTIMIZER_MODE=advise   # nudge instead of refuse (the pre-5.2 behaviour)
TOKEN_OPTIMIZER_MODE=off      # disable the hooks entirely
TOKEN_OPTIMIZER_LARGE_READ_BYTES=51200   # raise the "large file" threshold
If you want the tools without the enforcement:
claude mcp add --transport stdio --scope user token-optimizer -- \
  npx -y @ooples/token-optimizer-mcp@latest
Verify with claude mcp get token-optimizer, or /mcp inside Claude Code. Then
add the recommendations from integrations/AGENTS.md
to your CLAUDE.md — but be aware that guidance in a context file is advisory,
and models routinely read past it.
Installing the package changes nothing on your machine. Hooks and managed Claude Code, Codex, and OpenCode commands are wired by one explicit command:
npm install -g @ooples/token-optimizer-mcp@latest
token-optimizer-install
token-optimizer-install is the only thing that edits ~/.claude/settings.json; the install itself prints the path it would write and exits. The hooks it adds match nearly every tool call in every project on the machine, so that is not a side effect an npm install should have. Undo it with token-optimizer-uninstall, which is a dry run until you pass --apply. To activate as part of a container image or provisioning script, set TOKEN_OPTIMIZER_AUTO_INSTALL=1 before installing. Open a new shell to activate managed CLI commands, or use `tok
koala73/worldmonitor88kLive markets, conflicts, country risk, chokepoints, energy, and China decision signals. 90 tools.
AI 与智能体

 ahujasid/mcp-for-blender30k
Community plugin to control Blender 3D with any LLM of your choice. Not affiliated with the official Blender Foundation.
AI 与智能体

 oraios/serena30k
A powerful MCP toolkit for coding, providing semantic retrieval and editing capabilities - the IDE for your agent
AI 与智能体
 agentskills/agentskills26k
Search and discover Agent Skills from the skills.sh registry. Powered by HAPI MCP server.
AI 与智能体
 activepieces/activepieces25k
AI Agents & MCPs & AI Workflow Automation • (~400 MCP servers for AI agents) • AI Automation / AI Agent with MCPs • AI Workflows & AI Agents • MCPs for AI Agents
AI 与智能体

 czlonkowski/n8n-mcp23k
A MCP for Claude Desktop / Claude Code / Windsurf / Cursor to build n8n workflows for you
AI 与智能体