


Rip'n Fast. Fewer Tokens. Better Code.
The ripgrep of AI context. A map before your agent reads the repo — and a check on what it writes.
Ranked, deterministic call graph: what to touch, what it breaks, which tests to run. On the edit: blast
radius, tests that reach it, eleven quality kinds reporting only what got worse, forgotten co-changes, fields
read and written, names that resolve more than one way.
Just want to use it? Install it with the one line below, then start each coding session by telling your agent to
use it, for example: "Use ripwire on this repo." That is all most people need: the install also teaches your agent
when to reach for each command.
Want every detail? The reference guide near the bottom covers install, commands, output
format, exit codes and limits. You do not need it to get started.

Field report: what ripwire contributed to a large multi-agent coding engagement — written by Claude Fable 5.0, the frontier model orchestrating ~20 coding agents over two days on a ~1,500-file C++/Metal codebase. Click for the full report.
For a single developer, this tool is a good lookup accelerator. For an orchestrated fleet, it's load-bearing: it
halved the research spend, twice redirected tasks before wasted work, prevented at least one silent-divergence shipped
bug, and turned code-quality hygiene from a hope into a per-task mechanical gate. Whole-workflow ~2×; per-lookup
10–25×; and two moments where one call was worth more than the rest of the session's tooling combined.
— the report's bottom line
Text version of the report
Field report: what ripwire contributed to a large multi-agent coding engagement
Context, genericized: one orchestrating session directing ~20 sequential/parallel coding agents over a ~1,500-file
C++/Metal codebase across two days — a deep architecture audit, then a 14-task feature wave (new subsystems,
measurement infrastructure, a search-archive migration), ending in a verified all-on release flip. Every agent was
instructed to lead with ripwire for orientation and to close with its quality gates.
The headline numbers
- Roughly half the total token spend of the audit/research phase, saved. This is the operator's whole-phase
estimate — it includes everything the research agents did, ordinary file reads and all, which makes it conservative
rather than cherry-picked. The per-call factors underneath are much steeper: a single doc-recall call served the
relevant sections of a 164KB planning document in ~6K tokens (~25×), and agents that led with the tool ran ~30–40%
leaner on tool-call counts than agents doing raw read fan-outs over comparable questions.
- Two tasks had their direction changed by a single call. One task was chartered to activate a steering behavior
the team believed was in production; one
--callers query returned zero production callers, redirecting the
task to the real gap (the data provider that behavior needed had never been wired anywhere). Another task
refactored a widely-shared computation; --edit-check flagged 5 of 6 call sites as incompatible — sites a text
search had missed — that would otherwise have silently diverged from the canonical path the day the feature was
enabled, surfacing months later as an unexplainable visual bug.
- A dozen-plus real code-quality defects fixed, not waived, across ~15 implementing agents — all caught by
--quality-delta at each agent's "I think I'm done" moment: a 480-token duplicated routine, a fourth private copy of
a shared RNG utility, a hand-duplicated cost function, a pair of near-identical functions with a flipped sign
(correct at one boundary, quietly wrong at the other), test-fixture duplication across sibling suites, and functions
that had quietly absorbed a second job. None of these would have failed a test; all of them are the sediment that
rots a codebase under high-velocity multi-agent development. The gate made removing them routine instead of heroic.
Where the value concentrated
- Orientation and recall (the token win). Ranked-signature task orientation and section-granular document recall
meant agents started from answers, not file dumps. Recall over planning docs was the orchestrator's single
most-used verb — the audit's entire framing came from two calls.
- The contract checker (the shipped-bug preventions). Beyond the 5-of-6 catch above,
--edit-check gave
near-free proof-of-contract on every public-symbol change across the wave — the kind of verification that
otherwise simply doesn't happen at agent speed.
- The quality gate as a protocol. The measurable effect wasn't any single catch — it was that fifteen different
agents, none sharing context, all converged on the same "fix or justify with a written reason" discipline, with an
acknowledgments ledger that survived across tasks. Unattended orchestration usually leaks quality; here the
leak-check was mechanized.
- Persistent notes. Agents left gotcha notes pinned to symbols mid-wave (a caller-wiring law, an arming-rule
invariant), which later agents' lookups surfaced automatically — cheap institutional memory between contexts
that never met.
The honest boundary
- The engagement's deepest findings did not come from the tool. A structural capacity ceiling, a mis-derived
constant, a floating-point re-association drift of 1 ulp, and a seed-keying bug were all found by bespoke
measurement the agents built — baseline worktree diffs over full data fills, multi-arm attribution sweeps,
funnels. The tool is a floor for honesty and orientation, not a substitute for measurement design.
- Known false-positive mode, handled by its own documentation: the contract checker's arity heuristic
over-counts on defaulted trailing parameters (one task saw "incompatible=18" that were all fine). The tool's own
trust-calibration notes say to verify by compiling in exactly this case, and agents that followed them lost nothing.
- For broad, common-word conceptual queries, plain grep-and-read still occasionally won — consistent with the tool's
own guidance that it shines on specific technical asks.
Bottom line
For a single developer, this tool is a good lookup accelerator. For an orchestrated fleet, it's load-bearing: it
halved the research spend, twice redirected tasks before wasted work, prevented at least one silent-divergence shipped
bug, and turned code-quality hygiene from a hope into a per-task mechanical gate. Whole-workflow ~2×; per-lookup
10–25×; and two moments where one call was worth more than the rest of the session's tooling combined.
The model's own report of one engagement, on a version before 0.5; not a controlled measurement. Controlled
measurements are in docs/EVALS.md.
Fifty years of software-engineering results, and research from last month. 49 repositories and 71 papers folded — McCabe (1976) through to seven published in the last two months — each row in docs/LINEAGE.md naming the lesson taken and the file it lives in
Beside those sits a labelled survey of 237 tools that contributed nothing and says so. The two
sets are disjoint by construction, so they add rather than nest — a tool that gave a lesson is never
counted twice.
Both halves are load-bearing, and they are doing different jobs. The settled results are what
make the quality lens trustworthy: McCabe on complexity (1976), Halstead on volume (1977), Spärck
Jones on term specificity (1972), Nagappan & Ball on churn. Fifty years of replication means those
are not opinions, and a tool that measures your code should be built on the ones that survived.
The recent work is what makes it current: seventeen of the folded papers are from 2026, seven
published in the last two months and three in the last thirty days (dates as of 2026-09-08; every
row carries its arXiv id, so the claim is checkable rather than atmospheric). Retrieval for coding
agents, context-compression cost, placebo-controlled localization — that literature is months old,
not decades, and several rows were folded within weeks of the paper appearing.
Neither half alone would be enough. A tool built only on the classics would not know what an agent
needs; one built only on last month's preprints would have nothing underneath it. And the newest row
is a result that failed when it was tested here — which is the point of writing them down. All three counts are re-derived from that document's own tables by
test/readmedriftcheck.sh on every run, which fails if this page and those tables disagree, so the
claim cannot quietly drift. The row-by-row ledger is
docs/LINEAGE.md.
Languages: Rust · C++ · Objective-C/C++ · C · Metal · CUDA · Python · Go · Swift · TypeScript ·
JavaScript · Java · Ruby · PHP · Lua · Elixir · Dart · Kotlin · GDScript · Bash · C# · JSON · TOML · YAML · Markdown — see
language support and limits.
Latest: 0.6.5 — TypeScript alias imports resolve, and fixes from Windows testers. Release notes ·
the presentation · the changelog — with thanks to the
contributors named there; this release is largely theirs.

One process, no server — indexes this repository in 0.25 s using 6.6 MB, against 46.8 s and 391 MB for the graph-database MCP server it was measured against; warm queries answer in 197 ms to its 1,082 ms
Measured on 48 matched questions across django, webpack and this repository. Across all three,
ripwire indexes in 0.25–0.45 s and 6.6–16.5 MB against that server's 23–52 s and
391–623 MB. The full method, the wins named one by one and the losses included, is in
Against the leading graph-database code-context MCP server
and docs/EVALS.md.
One binary, offline — and the same line activates the skills for every agent it finds: Claude Code · Codex · Cursor · Windsurf · Gemini · opencode · aider
One self-contained binary on your own machine, offline, installed in one line — and the same line
installs and activates the task-shaped skills that teach your agent when to reach for it, not
just how, for every agent it finds on the machine. If your
agent can run shell commands — Claude Code, Codex, Cursor, Windsurf, Gemini, opencode, aider — it is
set up the moment the install finishes; the MCP server is the optional second
interface. Install it and ask it something before you finish
reading this page:
RIPWIRE_REPO=redhat-et/ripwire bash -c "$(curl -fsSL https://raw.githubusercontent.com/redhat-et/ripwire/main/scripts/install.sh)"
export PATH="$HOME/.local/bin:$PATH"      # where it installed; the installer prints this line if you need it
cd your-repo
ripwire . --for="<the change you are about to make, in words>"
Every install route (prebuilt, from source, per-agent skills, hooks, the MCP server) is in INSTALL.md.
Reach for the CLI first — it is the cheaper interface. The MCP server is the optional second
way in, and its convenience has a cost the shell pipe does not carry: its verb schemas sit in your
agent's context every session, whether or not it calls them.
The goal: one question, one complete answer.
Terminality is the objective. Ask the codebase a question and the answer should carry everything
you need — no follow-on grep, no three more whole-file reads to fill in what it left out. A call
followed by three greps is the same search paid for twice: it does not save you tokens and it does
not make the coding faster.
The two stair-steps that make it reachable — honest about what is missing, priced in what it spends
Two things make that reachable in practice, and neither is the destination. Answers are honest
about their own limits — a count that cannot be a total is labelled a floor, a zero means "none
found" and never "none exists", every truncation is disclosed — so an answer never looks more
complete than it is, and the map never degrades the code by guessing. And an answer can be given a
token budget, so what one costs is something you ask for rather than discover; where a complete
answer will not fit, it says it went over rather than silently dropping the row you needed.
Those two are the stair-steps: honest about what is missing, priced in what it spends. The step they
climb toward is a question fully answered in one call, which is not always trivial to reach — and
where it is not, the output says so rather than pretending otherwise.
How we measure the climb. A complete answer to every code question is genuinely hard, and it is
reached over many releases rather than in one. Until an answer can be complete, it owes you three
things: it stays bounded in size, it is fully honest about what it does not know, and it gives you a
clue where to look next. So every change is judged on more than "was it right":
- Complete answers: the share of questions answered so you can act without re-checking.
- Honest-partial rate: how often an incomplete answer says what it is missing, instead of
sounding confident.
- False-confidence rate: wrong answers that claim to be complete — the worst case, held near zero.
- Next-clue usefulness: for partial and wrong answers, whether following the answer's first
suggested next step reaches what the question needed, within one hop. Graded blind.
Answering comes first; efficiency is how we get there. We aim for answers about as lean as the
leanest tools, but a byte budget is never allowed to cost an answer. We have gone too far toward short
answers before and cut information that was needed, so now every size limit has one of two jobs: a
runaway guard far above typical answers (it catches an output bug, and says so when it trips), or a
stair-step target where anything over it must be explained. A capped answer is always measured
against the same answer uncapped, and the one that answers better wins.
Same answer, a fraction of the tokens — read this table first if your agent is on a budget
How these ten rows were measured — 2026-08-08, figures in ~tokens (≈ bytes/4), every ratio from a real run reproduced by the command in its row
Ten everyday moments, re-measured on this repository, 2026-08-08. Figures are ~tokens (≈ bytes/4);
every ratio comes from a real run, reproduced by the command in its row — raw byte counts and exact
commands in
docs/EVALS.md §5.
Ordered understand → navigate → review-the-change:
| Ask it | Command | ripwire | naive read | token savings |
|---|
| "Orient me in this repo" | ripwire . | ~5.6K tok | ~20K–25K tok — read README.md (+docs/ARCHITECTURE.md) | 3.6×–4.5× |
| "Where is X handled?" | ripwire . --for="…" | ~2.1K tok | ~4.9K–20K tok — grep -rn <term> src/, then read the file it points at | 2.3×–9.3× |
| "What do I already know?" | ripwire . --recall="…" | ~15K tok | ~445K tok — read all 119 markdown docs this repo carries | 29.2× |
| "Set me up for this task" | ripwire . --pack-task="…" | ~2.1K tok | ~16K–80K tok — read every relevant file, whole | 7.7×–37.7× |
| "Show me this one function" | ripwire . --expand=SYM --top-k=0 | ~260–16.5K tok body (+~5.7K for the ranked-neighborhood bundle) | ~43K–174K tok — read the whole file it lives in | 2.6×–670× |
| "Who calls this function?" | ripwire . --callers=SYM | ~580 tok | ~40K–52K tok — grep -rn SYM src/ (mostly noise), then open 2–3 files to sort real calls from mentions | 69.2×–89.1× |
| "Is it safe to change this?" | ripwire . --impact=SYM + --uses=SYM | ~1.3K tok | ~18K tok — open every direct-use file, whole | 14.4× |
| "I have a stack trace" | ripwire . --from-trace=FILE | ~1.4K tok | ~124K–298K tok — grep all 7 frame names, then open the innermost file(s) | 86.9×–208.6× |
| "I changed these files — tests? blast radius?" | ripwire . --situ | ~410 tok | ~3K–132K tok — git diff + grep -rn <syms> test/, then open the candidates | 7.3×–324.2× |
| "Review this PR/diff" | ripwire . --pr-context=REF | ~1.9K tok | ~4.8K–51K tok — git diff REF, then open the touched files | 2.6×–27.5× |
Same-correct-answer verification, and the honesty line these ratios come with
These aren't summaries that gamble with information. Each row is scored
same-correct-answer-or-it-doesn't-count, and both sides were checked, not assumed: orient surfaces
this repo's own pipeline files (ingest.cpp, graph.h, serialize.h) in the first screen, the same
three docs/ARCHITECTURE.md names as central; the --for row lands mcpStale
(src/mcpindex.h:633), the actual staleness check, 5th-ranked; --recall lands the container-rule
doc (AGENTS.md) that states, verbatim, the same "no std::map" rule CONTRIBUTING.md explains in
full; --pack-task names the same three touch points a human would — cachelint.h, mergeCachePack
(src/main.cpp:1787), the lintrules.h helpers it reuses; --expand --top-k=0 hands back the
requested function's complete, unmodified body — the ranked-neighborhood addition costs the same
~22.6 KB regardless of which function you ask for, confirmed on two (a fixed floor, not per-function
variance); --callers on langOfPath names its 2 real callers, the same ones a grep hit-list
buries under 5 files of comment-only mentions; --impact+--uses on coversOrEquals names the same
2 direct call sites --uses alone would, plus (disclosed) a transitive reach --uses doesn't cover
at all; --from-trace resolves all 7 frames of a real call chain by name to the same definitions a
per-frame grep would eventually find, mixed with call sites and comments; --situ on a 2-file diff
names the same 6 real test harnesses, 2 of which a filename grep across test/ cannot find even
after opening every one of its 41 candidates — a completeness gap, not just a byte one; --pr-context
surfaces co-change partners (test/regression.sh, src/main.cpp) a raw git diff has no way to
know were usually touched and weren't this time — Fowler's Shotgun Surgery checked rather than
merely named (the backtest is in docs/EVALS.md). The map ranks and discloses — it never paraphrases
your code — and every truncation is disclosed in the header.
The honesty line, made concrete: the same auto-selection behind the --expand row also runs the
other way. On a small file (pageRankDouble in src/pagerank.cpp, 5,559 B) the ranked bundle would
cost 27,916 B — nearly 5× more than the file — so ripwire serves the file itself instead, disclosed
as mode="whole-file" on the response, not silently.
docs/EVALS.md §7 lists that and the other counterexamples
this project publishes against itself.
Where those savings compound: an orchestrator that matches tasks to models — every lane it spawns starts cold on the same tree. The map is the one artifact that does not have to be rediscovered per agent, and the quality verbs hand a verdict back instead of a pile of files to re-read
The shape: plan the work, then run a loop that matches each task to the model that fits it. Every
thread it spawns opens with an empty context on a repository it has never seen. Orienting an empty
context to a large repository is the most repeated cost in the whole system, and the one this tool
was built for — it is also the cost that grows with the size of the tree, which is why the pattern
matters more the bigger the repository gets.
--for and --pack-task answer it in a single call, at the per-call rates in the table above,
instead of a grep-and-read tour that every lane pays over again from scratch.
The return path matters as much. --quality-delta, --test-gate and --edit-check answer what did
I make worse, which tests must run, did I change a contract — quantitative answers a lane can
hand back as a verdict, rather than a transcript the orchestrator has to read to find out what
happened.
What is and is not claimed here. Every figure on this page is a single-agent measurement. That
the saving compounds with the number of cold orientations follows from the fixed-cost mechanism, but
it is pre-registered and unrun — the reason the pattern is worth trying, not a result this
project has published.
See the map — not just the numbers
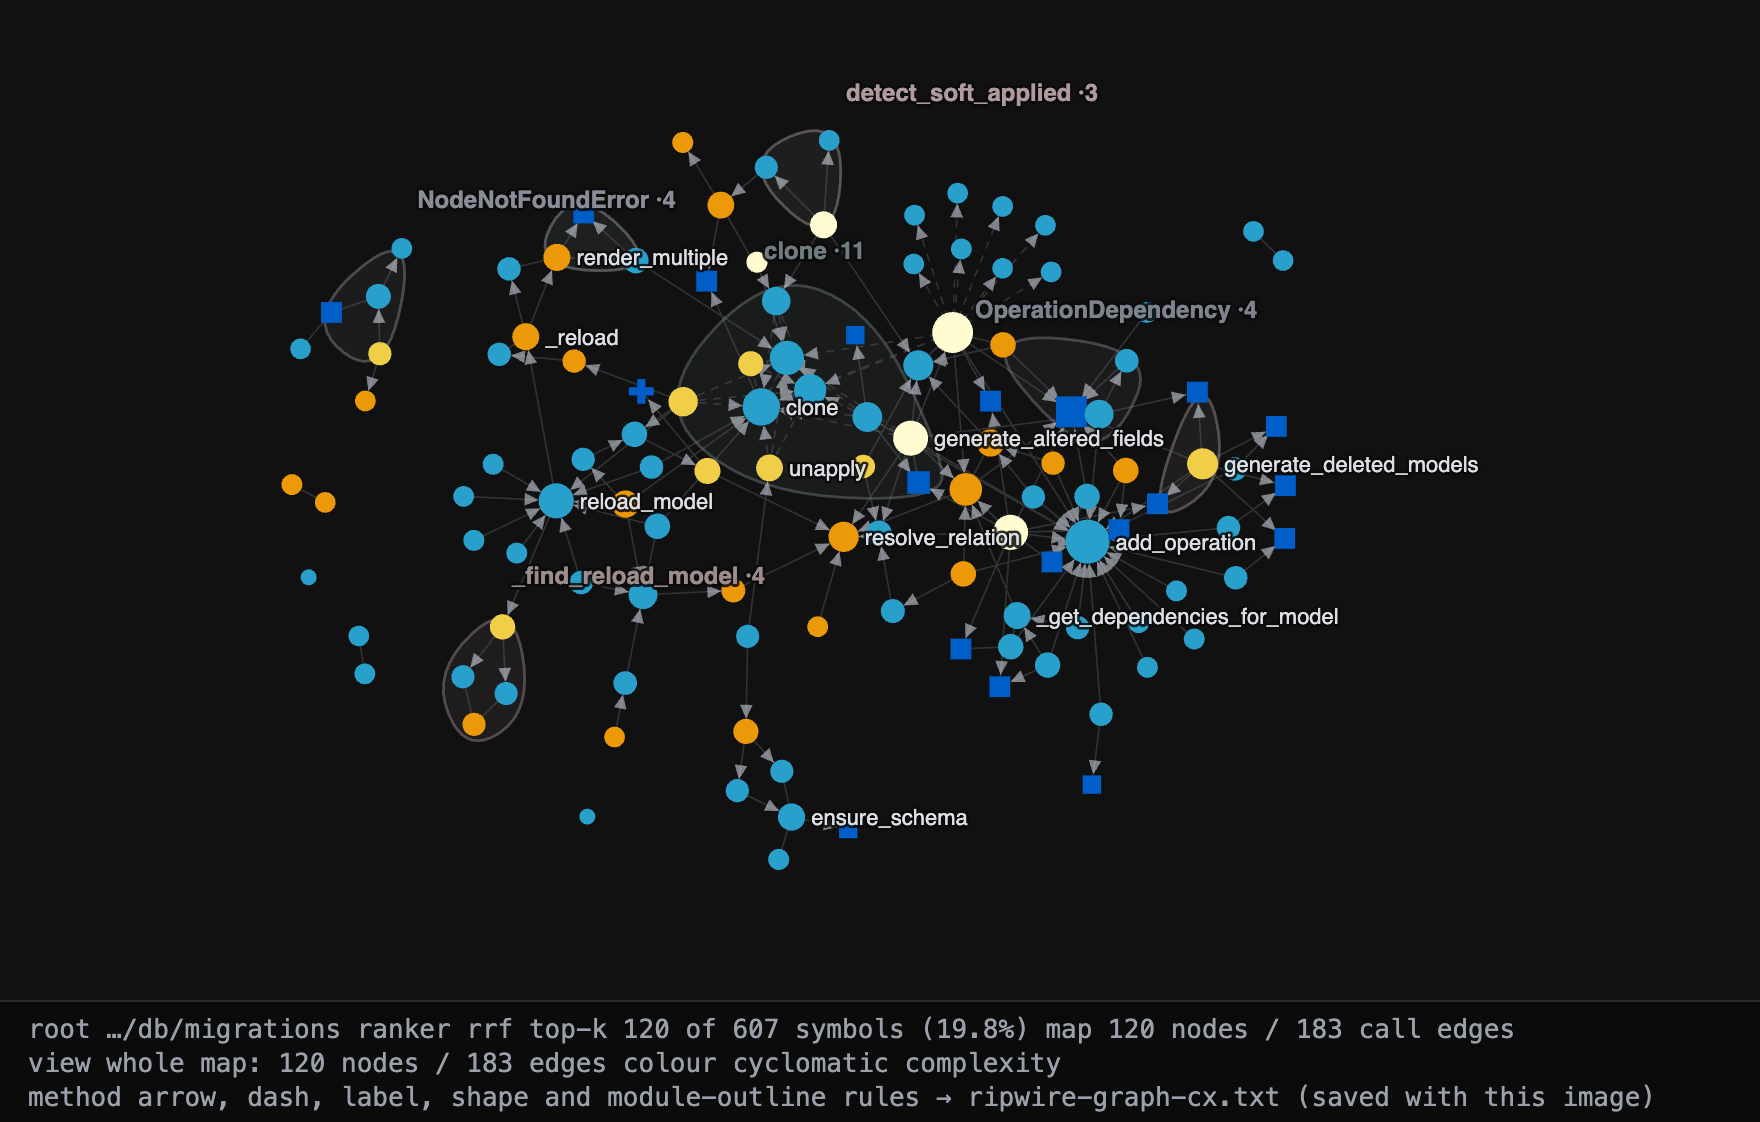
Django's migration autodetector, coloured by complexity. Thresholds are fixed, so the colour means the same thing on every repo you point it at.
ripwire path/to/django/db/migrations --rank-by=rrf --top-k=120 --color-by=cx --html=map.html
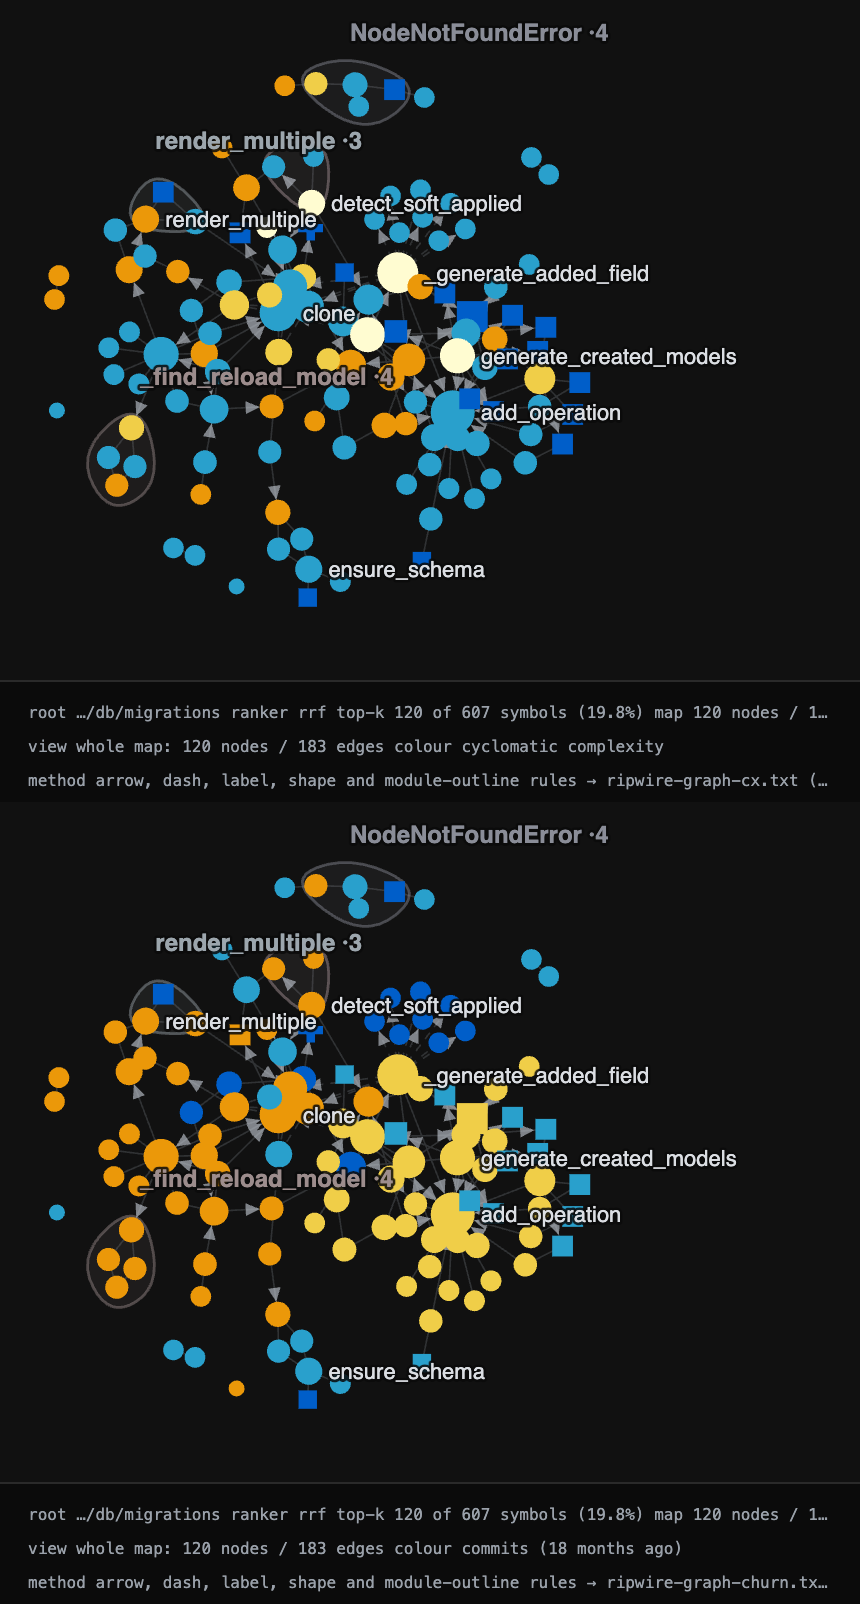 |
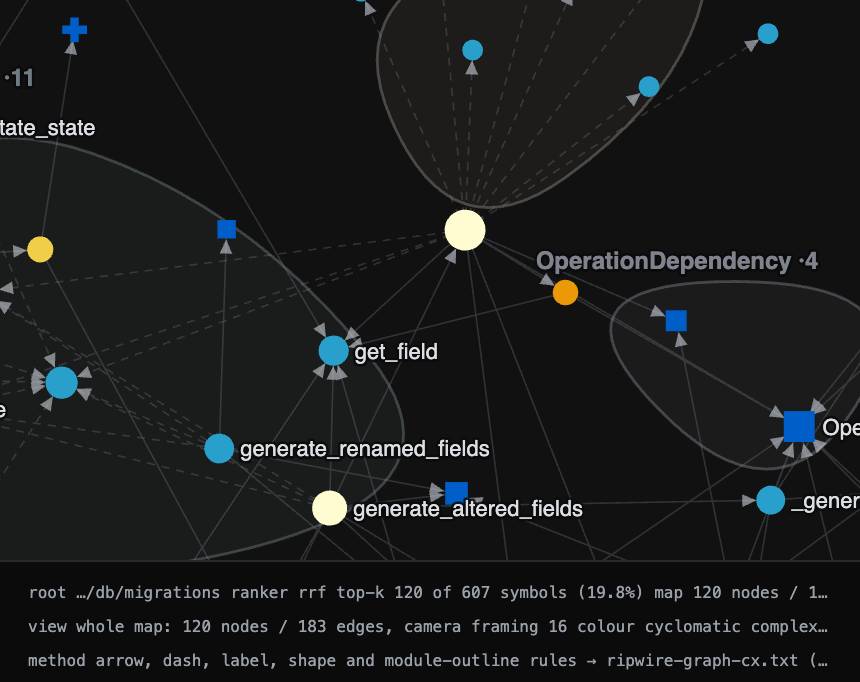 |
| The same graph, re-coloured by git churn. 76% of these nodes move to a different band — structure and history disagree, and one run shows you both. |
A dashed shaft is a guess. 31 of 183 edges here are one arm of a split the resolver could not choose between. No other tool marks which of its arrows it is unsure about. |
How to read these pictures — the five lenses, the fixed thresholds, and what the renderer refuses to draw
One self-contained HTML file (--html[=FILE]), no server, no CDN, no external asset. --color-by=lang|community|cx|churn|tested sets the initial colour; the page embeds all five and keeps a live selector, so switching lens costs no second run.
Read from the figures above, which state their own rules in a sidecar saved beside each image:
- arrow points caller → callee — the graph is directed, and the page draws it that way.
31 of 183 shafts dashed in this view = the resolver could not choose between same-name definitions and split the call over all of them — per edge, not per symbol. A symbol-level "this function makes some ambiguous calls" would mark every one of its edges, which would be a lie about most of them.- labels: top 24 by in-view degree, one per name — one label per distinct name, so a picture of a container class stops crowding out the functions you asked about.
- shapes: ● fn ■ cls ✚ var — kind is nominal data on a nominal channel; complexity never uses shape.
- module outlines:
7 of 12 modules with 3+ nodes in view (cap 12; 3 dropped as too thin to read as a region; 2 dropped as enclosing mostly other modules) — three separate truncations, each with its own count and its own reason.
The cx and churn ramps share one five-stop scale, ordered so lightness rises with the value — it survives greyscale printing, and every adjacent pair stays separable under protanopia, deuteranopia and tritanopia. Thresholds are fixed rather than per-corpus quantiles, so a hot node cannot be manufactured by a cold repository.
churn needs real git history: a shallow clone reports every file as one commit, and a directory with no repository says churn unavailable rather than drawing zeros.
One deterministic answer: the relevant symbols, their callers, the change risks, and
the tests that reach them. The task is yours to phrase — ask about your code, not ours. Run on this
repository (2026-08-30), ripwire . --for="incremental cache invalidation" produced about 4.3K
estimated tokens, not an enforced token budget. It includes:
This is what the output looks like, not the token-savings recipe. A bare --for on every question
is the most expensive way to use this tool — see Where it pays most
and the three controls below it.
What those 4.3K tokens actually contain — ranked symbols with their doc comments quoted in place, risk annotated on every row, one-hop callers, and the answer's own confidence=
- The ranked symbols, in rank order — the cache-header constant
kCacheMagic first (with its doc
comment quoted in place and the one next= call that opens it), then spanTierMemoPath (the
cache-path composer), ingestCommitTree, … ingest — each row with its file, line, and signature.
- Risk, annotated in place — complexity, git churn (
ingest shows 128 recent edits),
change amplification (touch ingest and 266 graph nodes feel it), purity and test coverage. The
fragile spots are visible before anything touches them.
- One-hop call context —
spanTierMemoPath calls shaKeyedCachePath, headSnapRepoHex,
exclConfigHex; no second query needed to see the neighbourhood.
- Its own confidence — this answer says
confidence="high" with the score margin attached; a
flat ranking says low, so it reads as a starting point instead of masquerading as an answer.
confidence= measures how clearly the ranking separates its head from the rest, not whether the
head is what you meant: ask a repository about a concept it does not contain and the best lexical
matches still rank, confidently. Phrase the task in your code's own words.
The actual wire format — what your agent reads (minified XML; trimmed and line-wrapped here)
<ctx task="incremental cache invalidation" confidence="high" margin_pct="20"
     bundle="compact" bodies="0" reason="compact-route" est_tokens="3995">
  <sigs shown="23" total="40" capped="1">
    <d l="106" n="kCacheMagic" p="src/ingest_cache.h" cx="0" in="0" churn="11" amp="71" pure="1" r="1"
       next="--expand=src/ingest_cache.h:kCacheMagic">
      <doc>incremental cache (--cache): per-file content hash + raw facts so a
           re-run re-parses ONLY …</doc>constexpr std::uint32_t kCacheMagic = …</d>
    <d l="1307" n="spanTierMemoPath" p="src/ingest_astquery.h" cx="1" in="2" churn="5" amp="44" r="2"> … </d>
    <d l="247" n="ingestCommitTree" p="src/dmm.h" cx="6" in="1" churn="6" amp="27" r="3"> … </d>
    …
    <d l="191" n="ingest" p="src/ingest.cpp" cx="4" in="14" churn="128" amp="266" tested="1" r="13"> … </d>
    … </sigs>
  <hops shown="2" total="6" capped="1" noedge="2">
    <h l="1307" p="src/ingest_astquery.h" n="spanTierMemoPath">
      <calls total="3"><c n="shaKeyedCachePath" l="1621"/> … </calls></h> … </hops>
</ctx>
cx= complexity, churn= git edit frequency, amp= change amplification, r= rank; <hops> rows
carry the one-hop call context, caps disclosed. The one legend at the top of the real output defines
them — tersely by default, every reading in full with --legend=full — and the root self-reports the
bundle's cost — est_tokens="3995" here.
| The agent without a map | The agent with ripwire |
|---|
| greps a common word, gets hundreds of hits across dozens of files | one ranked answer — est_tokens="3995" on this repository (re-derived 2026-09-05, the run above) |
| reads whole files to find the symbols that matter | those symbols, with complexity, churn and test coverage inline |
| finds the callers only if it thinks to grep for them too | callers, blast radius and the tests to run, in the same bundle |
| pays for every line it read, right or wrong | 5.0% of what that grep-and-read pass spends — on a 12-question set where it strictly satisfied 5 to the naive arm's 11 (re-derived 2026-08-23) |
Both halves of that sentence, because one without the other is an overclaim. The 5.0% is context
compression, not equal task completion: on the five questions both arms strictly satisfied, ripwire
spends 5.2% of what the naive pass spends. Cheap context that answers less is not a saving if the
agent then retries. The full adjudication, the four ranking defects behind the eleven-to-five gap, and
the run where this number got worse are in Measured.
58.3% of instances with all gold files in the top 10 — the best alternative lands 40.0%, while indexing in 0.31 s
And against five retrieval competitors on a held-out LocBench slice, it finds all gold files in
the top 10 on 58.3% of instances — the best alternative lands 40.0% — while indexing in 0.31 s.
The full leaderboard, losses included ↓
Against the leading graph-database code-context MCP server
Won 27 · lost 7 · tied 14 on 48 matched questions across django, webpack and this repository,
spending ~77K tokens against its ~486K for the whole sweep.
The full result, how it was measured, and where ripwire still loses
The 48 questions span symbol lookup, conceptual search, blast radius, and one-call task orientation.
ripwire indexes the same three repositories in 0.25–0.45 s and 6.6–16.5 MB, against that server's
23–52 s and 391–623 MB, and answers a warm query in a median 197 ms against its 1,082 ms. Its seven
wins are real and named one by one in the method.
Both arms warm with a pre-built index, median of 3 timed calls, stdout to a file rather than a pipe.
The competitor ran in its stronger retrieval configuration; its numbers were recorded once and then
frozen, and ripwire's side was re-run after the fixes the first pass produced. Per class, as a share
of the competitor's bytes on totals: symbol lookup 1.35×, conceptual search 1.23×, blast
radius 0.39×, task orientation 0.06×.
Where it loses: on a plain one-symbol lookup the competitor answers in about a kilobyte carrying
callers and callees, and ripwire spends roughly three times that to also hand back the body. It
ranks a chunk-id plugin first on one webpack query where ripwire never surfaces the directory at
all — a ranking miss, and a fix for it was built, met its pre-registered band, and was reverted
anyway for failing a separate standing requirement. Its depth-labelled blast radius and its import
edges are both better presentations than ripwire's flat reaching-set.
Full method, pins, per-class tables, the carried-versus-re-judged ledger, and the complete list of
what the competitor does better:
docs/EVALS.md §2.
Nothing it is unsure about reaches your agent unlabelled — unindexed languages named in the map's first line, a parse-health row on any file it cannot vouch for, every skipped file itemized with its reason
Nothing it is unsure about reaches your agent unlabelled — and nothing it could not see goes
unnamed. Every guess is marked in the output, and every mark has a next step — up to handing it a
compiler-grade index. Point it at a repository whose main language it has no grammar for and the
map's first line says so (unindexed="ml:793,mli:607,…" on a facebook/infer clone); a file it
indexed but cannot vouch for carries a parse-health row; every file the crawl passed over is
itemized with its reason. A confident-looking map that lies by omission is the failure mode this
tool refuses.
[What it misses, and what to run next →](#what-it-misses-and-what-to-run-next)
Graph-Ranked Retrieval: It finds the right files more often than the alternatives
58.3% against 40.0% for the best tool tested, and it answers before they finish indexing — N = 60 paired, zero exclusions, every arm re-run on one day
58.3% against 40.0% for the best tool tested — and it answers before they finish indexing. Every
arm below was re-run in full on 2026-08-08 — one ripwire binary (the profile-guided release build
that now ships), one evaluator, one 60-instance held-out LocBench slice: paired, zero exclusions,
same gold set, and the metric code imported unmodified into every arm. Strict file@10 = all gold files inside the top 10, which is whether
your agent starts in the right place at all.
| Round 4 — LocBench, Python-dominant | strict file@10 | any@10 | index (median) | query (median) |
|---|
ripwire --for | 58.3% | 85.0% | 0.31 s | 0.108 s |
| codebase-memory-mcp 0.9.0 | 40.0% | 63.3% | 1.24 s | 0.075 s |
| repowise 0.37.0 | 33.3% | 53.3% | 34.0 s | 1.159 s |
| graphify 0.9.34 | 31.7% | 46.7% | 7.82 s | 0.614 s |
| Aider repo-map 0.86.2 | 20.0% | 35.0% | (inside query) | 2.920 s |
| codeseek 0.1.31 (better of its two arms) | 15.0% | 20.0% | 3.37 s | 0.040 s |
Measured 2026-08-08, before the performance work that ships in 0.6.0. ripwire has become faster since — llvm-project's cold parse (182,555 files) fell from 194.1 s to 155.6 s of CPU, and --pack-task on a Go repository from 8.13 s to 5.88 s — but these timing columns have not been re-measured.
What this table costs us — six paired losses named, a runner-up we had under-credited at 26.7% and corrected to 40.0%, and the multi-file stratum no arm solves
Ripwire leads every arm on both accuracy metrics and in both strata. Paired, the losses are small and
they are published: 2 instances to codebase-memory-mcp, 2 to repowise, 1 each to graphify
and aider. Cold from nothing to an answer — parse, rank, reply, no cache — ripwire takes 0.213 s,
against a ~35 s index-then-query for repowise; its worst single index in this run was 352 s.
Three things this table costs us, said plainly. codebase-memory-mcp is the real runner-up at 40.0%,
not repowise — an earlier round credited it with 26.7%, and re-running it fairly raised it. The
margin over the best competitor is therefore 1.46×, not the 1.75× two separately-dated tables used
to imply. And multi-file gold is hard for everyone: ripwire leads the stratum at 21.4% strict, but
its own any@10 there is 78.6% — it finds a gold file and misses the siblings, and no arm in this
table solves that.
Held out wider — 243 instances across 78 repositories — ripwire lands 60.9% against 27.6%
for its own pre-routing baseline: +33.3pp paired, clustered-bootstrap 95% lower bound +25.0pp,
bought for +3.4% warm latency and −39.4% tokens. Full provenance, the losing instances one by one,
and a third round against a compression-layer competitor: Measured and
bench/headtohead/r4-2026-08-06/, whose harness is committed so
anyone can re-run the whole comparison.
Test scaffolding does not pollute the ranking from inside source files either: #[cfg(test)] mod tests, describe() blocks, Test* classes and [Fact] attributes are detected syntactically,
wherever they live — not by file path alone. On an astral-sh/ruff clone (5,945 files),
--ignore-tests removes 23,907 test symbols where path rules alone caught 18,532
(ripwire <ruff> --ignore-tests, 2026-08-14; the per-language fixtures are pinned by
test/testscopecheck.sh).
The table above, read two other ways. Every figure in both is one of its measured numbers; only the
manners and the cynicism are editorial. Should the reader find the manners excessive, the author begs
them to recall that the alternative was a second table.
📖 The same table, as narrated by Jane Austen
A Survey of the Neighbourhood's Eligible Instruments — being an account of five gentlemen of
retrieval, and one lady of no pretension whatsoever.
It is a truth universally acknowledged, that an engineer in possession of a large repository must be
in want of a map.
Mrs. Codebase-Memory must be named first, for she has risen a great deal in the estimation of the
neighbourhood — two-fifths of her answers entirely correct, which is more than any other caller can
say, and she is ready in a second and a quarter. It must nevertheless be recorded that her card
announces accomplishments in the semantic line; that upon enquiry the semantic line is not at home;
and that the household denies all knowledge of it. One is left with the impression of a capable woman
ill-served by whoever prints her cards.
Mr. Repowise is by common consent the most substantial of the party, and no one who has waited
upon him would dispute it. He is possessed of a handsome index and a manner of great thoroughness;
but he must be seen to. One does not simply address Mr. Repowise. One sends word, and dresses, and
waits — three-and-thirty seconds on an ordinary morning, and upon one memorable occasion in the
country, seven minutes and four seconds — during which interval a less consequential neighbour has
answered the question, taken her leave, and thought no more about it. He answers creditably when at
last he arrives, one time in three; whether that is worth the toilette, each family must determine
for itself.
Mr. Graphify enjoys a great many admirers. He does not rank his acquaintances; he calls upon them
in whatever order his walk happens to take him, and reports the order of the walk as though it were
an opinion. He has been known to arrive carrying a hundred and thirty megabytes of correspondence.
Pressed once for any answer at all, he replied that no matching nodes were found, and considered the
matter closed.
Mr. Aider is the most gentlemanly of the company and by far the most difficult to consult. He
cannot be asked a question — the thing is simply not done. One may mention names in his hearing and
hope he takes the hint; he does take it, and is fully ten points the better for it, which says more
about the hint than about Mr. Aider. But he forms his view of the neighbourhood before you speak and
retains it after, and one cannot escape the feeling that the conversation was never truly with you.
Mr. Codeseek is a young gentleman of quick habits who suffers from an affliction of address.
Speak to him plainly, in the language of ordinary complaint, and he will regard you with perfect
composure and say nothing whatever — nothing, upon sixty occasions out of sixty. Name a person
precisely as that person is named, and he grows animated directly. It is not stupidity; it is a want
of imagination in the matter of introductions.
And there is ripwire, of whom nothing is said in the drawing rooms, because she has already gone
home. She was asked; she answered, in thirteen hundredths of a second; every gold file within the
first ten, in eight-and-fifty cases of the hundred. She keeps no establishment, corresponds with no
distant authority, and has never once been indexed at a party. Mr. Repowise finds her abrupt.
She is.
Every figure above is a measured number from the round-4 table on this page: the index medians
(1.24 s, 34.0 s, 3.37 s) and repowise's 352 s worst case, the 40.0% and 33.3% strict file@10, the
0-results-on-60/60 fallback arm, the absent semantic_query tool, graphify's 129 MB
largest graph and its 1-of-60 empty ranking, aider's +10 pp personalization delta, and ripwire's
0.108 s / 58.3%. Provenance in bench/headtohead/r4-2026-08-06/
and docs/EVALS.md; only the manners are editorial. These are other
people's real work, and the joke is aimed at the trade-offs, never at the authors.
🕵️ The same table, worked as a case file — a private eye who trusts no index he didn't build himself
The Long Index — in which a man asks six informants one simple question, and only one of them has
the decency to answer it.
It was a million lines of somebody else's mistakes, and I needed one file out of it before the coffee
went cold. So I did what you do. I went and talked to the people who say they know the neighborhood.
Codebase-Memory had the best record in the room and she knew it — two answers right out of every
five, handed over in a second and a quarter, which in this business is practically a kindness.
Trouble was the card. Right under her name it said semantic query, real classy, real
expensive-looking. I asked to see it. She said it wasn't in. I asked the house. The house had never
heard of it. I've known a lot of good people ruined by whoever printed their cards.
Repowise was the heavyweight — everybody told me so before I got through the door. Big index,
good tailoring, thorough as a tax man. Only you don't just ask Repowise a question. You send word.
You wait. Thirty-three seconds on a good day, and one bad morning out in the country, seven minutes
and four seconds — long enough to get the same answer somewhere else, drive home, and forget his
name. He came through one time in three. For some outfits that's worth the wait. I've got a
metabolism.
Graphify never met a fact he wouldn't hand you. Ask him one thing and he turns up with a hundred
and twenty-nine megabytes of everything, unsorted, in whatever order he tripped over it — and he'll
report that order like it's a considered opinion. It isn't. Leaned on him once for anything at all;
he looked me dead in the eye, said no matching nodes, and figured we were square.
Aider was a gentleman, which is another way of saying you couldn't file a straight question into
him in triplicate. Wouldn't be asked. You mention things, loud, and hope — and sure enough, drop the
right names and he's ten points sharper, which tells you everything about the names and nothing about
Aider. He'd made up his mind about the place before I opened mine, and kept it after. You never did
feel the conversation was with you.
Codeseek was young and had a condition. Talk to him like a human being — plain, tired, the way a
man actually asks for help — and he'll look clean through you and say nothing. Sixty times out of
sixty, nothing. But name the thing exactly, badge number and all, and the kid lights right up. It
isn't that he's slow. He just never learned how people knock on a door.
And ripwire. Nobody at the table brought her up, on account of she'd already left. Took the
question, answered it in thirteen hundredths of a second — every file I needed inside the first ten,
fifty-eight times out of a hundred — keeps no office, wires no head branch, never once got herself
indexed at a party. Repowise says she's abrupt.
She is. That's why I hired her.
Every figure above is a measured number from the round-4 table on this page: the index medians
(1.24 s, 3.37 s, 34.0 s), repowise's 352 s / six-minute worst case, the 40.0% and 33.3% strict
file@10, codeseek's 0-of-60 plain-language arm, codebase-memory's advertised-but-absent semantic
tool, graphify's 129 MB largest graph and its 1-in-60 empty return, aider's +10 pp name-drop delta,
and ripwire's 0.108 s / 58.3%. Provenance in
bench/headtohead/r4-2026-08-06/ and
docs/EVALS.md; only the cynicism is editorial. These are other people's
real work, and the joke is aimed at the trade-offs, never the authors.
Name a symbol and it is the first hit — routing lifts recall@1 61.1% → 91.3%; route everything to the name lane and prose queries collapse 0.967 → 0.016 MRR. Both numbers ship together
Name a symbol and it is the first hit — and it is never a mystery which ranker answered. Every
--for query is served by one of three lanes; a confidence-gated router picks by reading the
query's shape, discloses its choice on the output (route=), and --no-route overrides it.
Routing lifts recall@1 on name-shaped queries 61.1% → 91.3% in src/, 59.2% → 85.5% at the
repository root — and the gate is load-bearing in both directions: route everything to the name
lane and prose queries collapse from 0.967 MRR to 0.016. Both numbers ship together. Reproduce
with ripwire <dir> --eval-retrieval, which grades EVERY doc-commented symbol in the corpus and
prints its own population=/scored=/rule=; the full per-ranker tables are in
bench/ANSWERQUALITY.md.
| Lane | Built for | Why it wins there | Where it loses |
|---|
| name-exact | identifier-shaped queries (chooseForRanker, pack task) | whole-name match ignores body noise: 91.3% recall@1, 0.960 MRR in src/ | scores zero on any word that is not literally a name — forced onto prose it dies (0.016 MRR) |
| subtoken+body | prose and task queries ("where is the content hash computed") | the only lane that matches vocabulary living in doc comments and bodies | exact names drown in shared subtokens (61.1% recall@1 on name queries) |
| mention anchor | a pasted path, Type.method, or issue URL | a literal mention is lifted above any score — paste the ticket, don't paraphrase it | adds nothing when the query names no artifact |
How each lane finds things, and how the router picks — step by step
How the conceptual lane finds what you didn't name. The subtoken+body lane is why a query with
no symbol name in it still lands:
- Both sides are split into subtokens.
SplitChunksPlugin becomes split+chunks+plugin, and
so does your query — so words match pieces of names you never typed.
- Three evidence fields, not one. A symbol is scored on its name subtokens, its doc comment, and
its body — vocabulary that only exists in a comment or an implementation still finds its symbol.
- BM25 with per-query IDF. Rare, discriminating words dominate the score; words the whole corpus
shares contribute almost nothing. Type the three words only the right function uses and they carry
the query.
- Lookalikes are down-weighted, not hidden. Fixture, test-data, and generated paths score at a
fraction, so a test vocabulary-twin cannot outrank the real source (adversarial-class pollution@5:
28% → 0%,
docs/EVALS.md §4) — but they stay in the index and are still found when asked for.
- The list ends at a cliff, not a quota. The cut is adaptive: output stops where the scores drop
off, so a sharp answer is a short list and a diffuse one is disclosed as such, instead of a fixed
top-k padding both.
How the router picks. The gate is built on cheap, corpus-derived evidence, and its bias reflects
an asymmetry the table above makes plain: a missed name-route costs a few ranks; a false one is
catastrophic (0.016 MRR).
- Identifier shape is trusted outright. A camelCase/snake token — or a short query carrying
one — routes name-exact. Someone who types
chooseForRanker is naming, not describing.
- The all-words test. If every content word equals some symbol's whole name (
pack task
where both pack and task are real symbols), that is strong evidence of a name query.
- The plausibility test. Present is not enough — each matched name must be specific: few
definitions, and not a subtoken carried by half the corpus's symbol names (thresholds derived
from the index itself, not a hardcoded stdlib list). This is what catches
split chunks:
every word names a symbol, but split names a String method defined everywhere — so the route
is declined and the conceptual lane runs, which finds SplitChunksPlugin easily.
- Every decision is disclosed.
route= states the lane that ran; a decline names the anchor
that failed and why. --no-route forces the conceptual lane when you disagree.
The proof the gate earns its keep: the routed lane matches the best single lane on both query
modes simultaneously — 0.960 MRR on names (equal to forced name-exact) and 0.967 on prose (within
noise of pure subtoken+body, src/). No single lane does that.
The honest boundary: the router classifies the query's shape — it cannot rescue vocabulary that is
not in the index. A prose query whose concept lives only in a compound class name
(SplitChunksPlugin contains no splits subtoken) is correctly sent to the conceptual lane, which
then has little to grab; that gap is measured and recorded in
docs/EVALS.md §7, not hidden. Numbers re-derived 2026-08-08 on this tree;
per-lane table and history in docs/EVALS.md §4.
Saves Tokens: It answers for a fraction of the context
5.0% of what a grep-and-read pass spends — 5.2% on the questions both arms fully answered, and a dedicated context compressor run over the output saved exactly 0 tokens
On mid-task questions it had never seen, ripwire answers at 5.0% of what a grep-and-read pass
spends — 5.2% on the questions both arms fully answered. --pack-signatures returns 74.7%
fewer bytes than full bodies at top-50 (re-derived on this tree, 2026-09-06). The output is already
dense enough that running a dedicated context compressor over it saved exactly 0 tokens.
Why both figures are printed — 7.3% → 5.0% overall, but 1.7% → 5.2% on the questions both arms answered
Both of those first two figures moved when they were re-derived on 2026-08-23, and they moved in
opposite directions — 7.3% → 5.0% overall, but 1.7% → 5.2% on the both-answered subset. Same
frozen questions, same frozen verb ladders, same corpus pin, same tokenizer; the naive arm reproduced
to the token. What changed is where ripwire spends: the compact conceptual route made its misses
much cheaper, while richer default bundles made the questions it answers dearer. Both numbers are
printed because printing only the one that improved would be the failure this project exists to not
commit. The full per-question re-derivation is in the Round 3 note under Measured.
It is also cheap enough to call on reflex: this repository parses in ~0.15 s cold and ~0.10 s
warm (time ./build/ripwire . --no-cache), so the agent asks instead of guessing.
Where it pays most, and where it does not
A map is a fixed cost paid once per context — strongest of all under an orchestrator that matches tasks to models: every lane it spawns starts cold on the same tree. It pays again on the checking pass, and it does not pay on a question one grep already answers
A map is a fixed cost paid once per context, so it pays in proportion to what that context goes on
to do with it. Two shapes get the most out of it, and one gets nothing.
- Orienting a context that does not know the repository. This is the strongest case, and it is
strongest of all under an orchestrator that matches tasks to models: every lane it spawns starts
cold on the same tree, and each one would otherwise re-derive the same structure from scratch. The
map is the one artifact that does not have to be rediscovered per agent.
- The checking pass at the end.
--quality-delta, --test-gate and --edit-check answer
questions — what did I make worse, which tests must run, did I change a contract — that an agent
cannot answer by reading more source, at any budget.
- It does not pay on a question one
grep already answers. The map is charged whether or not it
was needed, so a narrow lookup in a file you can already name is cheaper without it. --help-task
exists to make that call, and a flat ranking says confidence="low" rather than pretending.
Getting the saving takes three things, and a bare --for is none of them.
The three controls that decide what it costs — a budget (--token-budget / --top-k), routing (--help-task), and the skills that teach an agent when not to reach for it
- A budget.
--token-budget=N caps the bundle; --top-k=N caps the rows of the default map,
--query, --format=candidates, --recall and --graph-query — it does not shape plain --for.
On --for, a positive, explicit --top-k is read by nothing: the run prints a stderr note
(--top-k is not read by --for) and still emits the full bundle. Two neighbours of that shape are
different and neither warns: --for --format=candidates --top-k=N does consume the flag (the
candidate export composes with it and caps the rows), and --for --top-k=0 is refused outright by the
payload-only guard (--top-k=0 needs a payload verb), not warned-and-emitted. Narrow plain --for
with its own arguments instead — --signatures-only
(drop the auto-bodies), --token-budget=N (shapes the bundle to fit), --detail=N (full bodies for
just the top N). Unbudgeted --for returns
a rich terminal bundle by design — right when it ends the question, wasteful when it does not.
- Routing.
ripwire . --help-task="<task>" names the ONE command the task actually wants, and
abstains when the evidence is thin. It is advice, it never runs anything. An answer of "just grep
for it" is a correct answer and the tool will give it.
- The skills.
skills/install.sh teaches an agent when to reach for which verb. Without them
an agent has 175 flags and no map of which moment each is for, and it will reach for the map every
time — including the times it should not.
The invocations first-time users get wrong — WRONG → RIGHT, each row a real failure reported from the field
| WRONG | RIGHT | why |
|---|
ripwire . --for="…" --top-k=5 | ripwire . --for="…" --signatures-only (or --token-budget=N, --detail=N) | --top-k is inert on --for: the run warns on stderr and emits the full bundle anyway, so the agent believes it narrowed the output and did not. |
ripwire . --query="…" as the default lens | ripwire . --for="…" | --query is the raw BM25 ranking — the binary's own help calls it debug and says "use --for". It is the right tool for hunting a vocabulary, the wrong default for a task. |
ripwire . --expand=SYM where SYM is an ambiguous bare name | ripwire . --expand=SYM --top-k=0 (or name it exactly: --expand=FILE:NAME) | A multi-match name keeps the ranked map — there IS something to disambiguate — so ~9K est_tokens of map ride along with the bodies. An unambiguous single match already defaults to --top-k=0 on its own (disclosed as topk_default="0"); no flag needed there. |
--callers=<route handler> expecting routes | find the URL in the project's own docs (e.g. a feature map), then --expand the handler | Framework route handlers have no callers in the graph — the decorator reaches them, not project code. Empty --callers on a handler is the design, not a bug. |
ripwire <dir-of-repos> … (ONE root that happens to contain checkouts) | cd into ONE checkout first | Nothing refuses this: the crawl silently walks the nested repos and merges them into one corpus, so you pay for a map of everything and rank across unrelated codebases. Distinct from the real multi-root feature, which is N explicit positional roots (ripwire dir1 dir2 … <verb>, 2–16 checkouts merged on purpose). |
What ripwire does not replace — reach for grep/read here even when a verb looks close:
| still use grep/read for | why |
|---|
| route → handler lookup from a URL | ripwire ranks symbols, not URLs; it does not know your routes |
| templates, i18n catalogs, SQL migrations | not call-graph territory |
| one exact string in one file you can already name | --grep=TERM works, but rg is fine too — and the map is a fixed cost you did not need |
| UX flow through frontend event handlers | the JS is in the graph, but the flow needs line context, not a ranking |
What is measured and what is not — these are single-agent figures; that the saving grows with the number of cold orientations is pre-registered and unrun, not a published result
What is measured and what is not. The per-question figures above and in Measured are
single-agent measurements. That the saving grows with the number of cold orientations follows from the
fixed-cost mechanism but is not a published result — it is pre-registered and unrun. Treat the
single-agent numbers as the measured ones.
Better Code: It automates the review judgments nobody has time to make — every lens from published research
Six independent evidence families, each implementing published work — the largest correlation between any two is +0.168, which is what makes agreement corroboration rather than one metric counted twice
--quality-panel runs the calls a good reviewer makes by hand — is this function too tangled, is it
named badly, does it hide control flow inside an idiom, does its history say it keeps breaking, must
you read five other files to follow it, does it mutate state three hops away — as six independent
evidence families, and ranks by how many of them agree, never as one blended score. Each family
implements published work — McCabe on shape, Butler on naming, Gopstein's atoms of confusion on
idiom, Nagappan & Ball on churn, Beck & Diehl on colocation, Henry & Kafura on state — with the
lesson taken from each paper, and the rules measured and withdrawn, in
docs/LINEAGE.md. Pooled over five corpora (n = 27,889) the largest correlation
between any two families is +0.168: they really are measuring different things, so two families
firing on the same function is corroboration rather than one metric counted twice.
Why this matters most for code an agent wrote — empty-catch masking +47%, rewritten-within-two-weeks +15%, and reuse declining
That matters most for code an agent wrote. Empty-catch error masking is +47% more common in
AI-authored commits, a function rewritten again inside two weeks +15% more likely, and reuse is
declining as AI's share of commits grows (GitClear, AI Copilot Code Quality, 2026). Ten of
--quality-delta's 11 kinds each target one measured mode like those (the eleventh, placeholder,
lists the stubs and TODOs a change adds, and never gates), and it reports only what your
change made worse — then --exemplar shows the pattern in your own repo to copy, and --test-gate
names the tests that must run before "done."
Reproducing all of it — dated, sourced measurements in docs/EVALS.md, each with its instrument, its corpus and its counterexamples, because the losses ship beside the wins
Tree-local numbers above are reproducible with the commands shown; the rest are dated, sourced
measurements in docs/EVALS.md — each with its instrument, its corpus, and its
counterexamples, because the losses ship beside the wins. Zero runtime dependencies, C++23, builds
with the network off.
Built for Codex, Claude Code, Cursor, Windsurf, Gemini, opencode, aider, and any agent that can
call a CLI.
What comes back — real output from this repository, pretty-printed and trimmed (re-captured 2026-09-05; rows are served in rank order, each naming its file)
<ctx task="incremental cache invalidation" route="subtoken+body" confidence="high" margin_pct="20"
bundle="compact" bodies="0" reason="compact-route" est_tokens="3995">
<sigs shown="23" total="40" capped="1">
<d l="106" n="kCacheMagic" p="src/ingest_cache.h" cx="0" ccx="0" in="0" churn="11" amp="71" pure="1" r="1"
next="--expand=src/ingest_cache.h:kCacheMagic"><doc>incremental cache (--cache): per-file content hash + raw facts so a re-run re-parses ONLY c…</doc>constexpr std::uint32_t kCacheMagic = 0x4b505443</d>
<d l="1307" n="spanTierMemoPath" sc="rw" p="src/ingest_astquery.h" cx="1" ccx="0" in="2" churn="5" amp="44" r="2"><doc>Composed exactly the way every OTHER blob family is (quality.h): one fixed-width identity hex pe…</doc>inline std::string spanTierMemoPath( const std::string& diskPath )</d>
<d l="247" n="ingestCommitTree" sc="rw::dmm" p="src/dmm.h" cx="6" ccx="5" in="1" churn="6" amp="27" r="3"><doc>Ingest the tree at `sha`, materialized out of `root`'s object store. …</doc>inline bool ingestCommitTree( const std::string& root, const std::string& sha, … )</d>
<d l="841" n="mcpRefreshedThisRequest" sc="rw" p="src/mcpindex.h" cx="1" ccx="0" in="2" churn="20" amp="43" r="4"><doc>P1-15 — the `_reingest` envelope field for a response whose handling ran an INCREMENTAL pass, …</doc>inline bool mcpRefreshedThisRequest( std::uint64_t passesAtEntry )</d>
…
</sigs>
<hops shown="2" total="6" capped="1" noedge="2">
<h l="1307" p="src/ingest_astquery.h" n="spanTierMemoPath">
<calls total="3"><c n="shaKeyedCachePath" l="1621"/><c n="headSnapRepoHex" l="1359"/><c n="exclConfigHex" l="1554"/></calls>
</h>
<h l="247" p="src/dmm.h" n="ingestCommitTree">
<calls total="10" shown="7" capped="1">…</calls>
</h>
</hops>
</ctx>
The cache cluster, ranked and annotated in place: cx/ccx complexity, in reuse count, churn
recent commits, amp change amplification, tested coverage — the fragile spots are visible
before the agent touches them, in a few thousand tokens (est_tokens="3995", self-reported in the
header) instead of five whole files. This is a conceptual query, so the bundle is the compact
shape: the ranked map plus one-hop callee edges, no inline bodies, and the root says so rather than
leaving you to notice. Read the map, then --expand=SYM the one you want — or pass --auto-bodies
to get bodies inline as before.
What the quality panel shows — real output from this repository, trimmed (legend comment elided)
$ ripwire . --quality-panel --limit=1
<quality_panel preset="default" families="6" enabled_n="6" cut="2" eligible="6497" ranked="524" …>
<s p="src/graph.h:723" n="buildGraph" fam="4" of="6" fired="structural,confusion,historical,colocation">
<e f="structural" counted="1" why="ccx=764 loc=1368 nest=8 humps=34 deep=315 ev=98 rrank=1"/>
<e f="confusion" counted="1" why="atom-embedded-crement*4"/>
<e f="historical" counted="1" why="hrank=12 churn=36"/>
<e f="colocation" counted="1" why="crank=32"/>
</s>
…
</quality_panel>
Four of six independent evidence families corroborate on buildGraph, each with its own reason
shown inline — never a single blended score. eligible="6497" narrows to ranked="524" (2-of-6
agreement): an 8.1% shortlist of this repository's own functions, not a guess (re-derived
2026-08-23 — the corpus grew, the shortlist share did not move). Full six-family breakdown, real
numbers per family → The quality panel below.
Full retrieval tables — including the MRR figures behind the router numbers above — in
bench/ANSWERQUALITY.md and Measured.
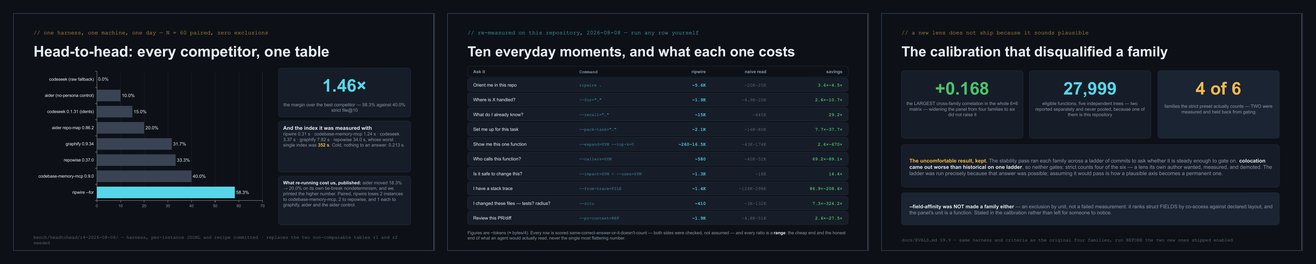
▶ The whole tool in 36 slides — every figure names the instrument that pins it
renders in your browser · pptx beside it · the numbers behind it
What it answers · Quickstart ·
The quality panel · Benchmarks ·
Honesty contract ·
Agent setup · Docs
What it answers
185 long flags across seven families, plus the MCP server — and --help-task names the ONE command a task wants, or abstains honestly when the evidence is too thin
Around the core sit 185 long flags advertised in --help, across seven families — plus an MCP
server, so a coding agent can call any of them mid-task instead of grepping and reading whole files.
--help prints one line per flag (~4.5K tokens); --help=--FLAG prints that flag's full entry with
every caveat, --help=SECTION one family, and --help=all the whole catalog.
Not sure which of them fits the task in front of you? ripwire . --help-task="<task in words>"
recommends ONE executable command with the evidence behind the pick — advice only, it never runs
the recommendation — and abstains honestly when the evidence is too thin to name a winner.
Which surface is the authority — --help vs docs/COMMANDS.md — and the four reflex verbs worth memorising
./build/ripwire --help is generated from the binary's own flag table and is always the authority;
docs/COMMANDS.md documents every one of the 176 documented flags — 162 of them
with a real invocation and its recorded output (both counts are reported by the generator that writes the
document, docs/docs_commands_build.py, and were re-derived from it on 2026-09-14;
test/docscommandscheck.sh fails if that documented set and the binary's own flag table ever disagree). Each family below links there.
Four reflexes worth wiring into muscle memory: --from-trace=FILE for an error you have in hand,
--edit-check=SYM right after an edit (did the contract change, and which callers are now provably
incompatible), --merge-scout=REF1,REF2 before landing parallel branches, and --pack-task="…" for
ranking, bodies, callers and tests in one budgeted bundle.
| Family | The question | Representative flags |
|---|
| understand a codebase cold | "What is this repo, and what matters in it?" | --for · --help-task · --tree · --lego · --exemplar · --recall · --top-k · --token-budget · --max-tokens |
| navigate / answer a question | "Who calls this? Is it safe to change? Which tests?" | --callers · --callees · --uses · --impact · --path · --connect · --affected · --situ · --test-gate · --grep |
| zoom the detail ladder | "Show me more — but only where it pays." | --detail · --pack-signatures · --outline · --expand · --compress |
| assess quality / structure | "Where is the risk, and did I just add some?" | --quality-panel · --hotspots · --clones · --metrics · --deps · --lint · --quality-delta · --dmm · --edit-check · --pr-context · --merge-scout |
| self-diagnosis | "Is my setup actually working?" | --doctor |
| security | "Is this agent skill file safe to install?" | --scan-skill · --scan-skills |
| knobs / modes | shape, format, cache, budget | --json · --format · --mcp |
Quickstart
Prebuilt binary — macOS on Apple silicon and Linux (arm64 / x86-64, built for RHEL 8+), SHA-256 verified, shipping seventeen agent skills the installer activates for every agent it detects
Prebuilt binary — macOS (arm64; 0.6.1 is the last release with an Intel macOS binary, and an Intel Mac
builds later releases from source) and Linux (arm64 / x86-64, built for RHEL 8+;
every release is smoke-tested on a RHEL 9 userland before it publishes). Downloads the latest
GitHub Release, verifies its SHA-256, and installs
to ~/.local/bin. From v0.2.2 the release tarball also ships the seventeen agent skills, and the
installer stages them under ~/.local/share/ripwire/skills and activates them for every agent it
detects (Claude Code, Codex), printing one line per agent saying what it did. Sixteen of the
seventeen are for using the tool; the one about compiling ripwire itself (ripwire-opt-remarks,
audience: contributor in its front matter) stays staged unless you pass --contributor to
skills/install.sh. An agent that is not
installed is never given a skills directory, hooks are never registered without an explicit --hook,
and RIPWIRE_NO_ACTIVATE=1 stages without activating for image builds. When no agent is detected the
activation one-liner is printed instead:
RIPWIRE_REPO=redhat-et/ripwire bash -c "$(curl -fsSL https://raw.githubusercontent.com/redhat-et/ripwire/main/scripts/install.sh)"
export PATH="$HOME/.local/bin:$PATH"      # not on PATH by default on macOS or most Linux shells; add it to your rc file
Windows x64 (preview) — a zip with ripwire.exe and the skills, no runtime to install first; a preview until Windows users confirm it
Windows x64 — preview. From 0.6.3 each release carries ripwire-<version>-windows-x64.zip and its .zip.sha256.
It is built with clang-cl against the static C runtime, so it needs no Visual C++ Redistributable, and like the Linux
x64 binary it needs an x86-64-v3 (AVX2) CPU. CI unzips and exercises it on every train, including a byte-for-byte
comparison of its output with Linux's, but no maintainer runs Windows, so treat it as a preview until Windows users
report back. The exe is not code-signed. Expand-Archive does not pass the download's Mark-of-the-Web on to the
files it extracts, so SmartScreen does not prompt for an exe unpacked this way; no prompt is not a verdict. In PowerShell:
$v = "0.6.3"; $a = "ripwire-$v-windows-x64"; $u = "https://github.com/redhat-et/ripwire/releases/download/v$v"
Invoke-WebRequest "$u/$a.zip" -OutFile "$a.zip"; Invoke-WebRequest "$u/$a.zip.sha256" -OutFile "$a.zip.sha256"
# extracts only when the SHA-256 matches; on a mismatch it throws and nothing is unpacked
if ((Get-FileHash "$a.zip" -Algorithm SHA256).Hash -eq (Get-Content "$a.zip.sha256").Split(" ")[0]) { Expand-Archive "$a.zip" -DestinationPath "$env:LOCALAPPDATA\Programs" } else { throw "SHA-256 mismatch: do not run $a.zip" }
$bin = "$env:LOCALAPPDATA\Programs\$a"
[Environment]::SetEnvironmentVariable("Path", "$bin;" + [Environment]::GetEnvironmentVariable("Path", "User"), "User")
$env:Path = "$bin;$env:Path"   # this window too; new windows read the user Path
ripwire --version
- The hash check passes because
-eq ignores case: Get-FileHash prints upper-case hex and the .sha256 file
is lower-case. For a case-sensitive compare, use .Hash.ToLower() -ceq.
- Comparing two outputs in Git Bash: use
cmp. There fc is a shell builtin (it replays history) and compares
nothing; the Windows tool is fc.exe, run as MSYS_NO_PATHCONV=1 fc.exe /b a b so /b is not rewritten as a path.
- Git for Windows is needed for the git-history features (churn,
--situ, the git row of --doctor) and for
the skills installer. The map itself runs without it.
ripwire . --doctor: every row should read ok="1". binary-path finds ripwire the way PowerShell does
(Path in order, then PATHEXT). When it fails, which= names the ripwire that Path finds first, and
which_version= is what that one prints for --version. same_bytes="unknown" means a copy could not be read;
the row fails as unverified, so compare the two with Get-FileHash. The cache lives in %LOCALAPPDATA%\Temp\ripwire-<uid>
(your TEMP). With TMPDIR, TEMP and TMP all unset, Windows' own temp-directory rule falls back to your profile
folder, so the cache is %USERPROFILE%\ripwire-<uid>; the cache-dir row names the directory either way.- Checking cache reuse: in PowerShell
$env:RIPWIRE_CACHE_STATS=1; ripwire . > $null (in Git Bash
RIPWIRE_CACHE_STATS=1 ripwire . > /dev/null) prints one cache-stats line on stderr. Run it twice with no other ripwire build in between: reparsed=0 and reused= equal to files= mean every
file came from the cache. warm_growths= is a performance counter, not a reuse fact: it counts how often a worker
thread's buffer had to grow, which depends on how the threads split the files, so it varies from run to run by design.
- Agent skills (Claude Code, Codex): from Git Bash, in the unzipped folder,
bash skills/install.sh (Claude Code)
or bash skills/install.sh --codex. From PowerShell, name Git Bash by full path,
& "C:\Program Files\Git\bin\bash.exe" skills/install.sh: a bare bash there is often WSL's
(C:\Windows\System32\bash.exe), which installs into the WSL home, where Windows agents never look. Or copy them by hand in PowerShell:
New-Item -ItemType Directory -Force "$HOME\.claude\skills" | Out-Null; Copy-Item -Recurse -Force "$bin\skills\ripwire-*" "$HOME\.claude\skills\"
(Codex reads $HOME\.agents\skills). --hook is untested on Windows, and scripts/install.sh (the curl installer) does not run there.
Building it yourself needs CMake 3.24+ and a C++23 compiler, and nothing else installed first —
every dependency is vendored in-tree, so the build completes with the network off.
git clone https://github.com/redhat-et/ripwire.git
cd ripwire
cmake -S . -B build && cmake --build build -j
./build/ripwire . --max-tokens=3000   # the ranked map — start here on an unfamiliar repo (bare it is ~22 KB here; this keeps the head at ~6 KB)
Why there is no download step — vendored grammars, the offline-build proof, the languages parsed, and putting it on PATH
Or build from source. Requirements: CMake 3.24+ and a C++23 compiler — that means clang 16+ /
AppleClang 15+ (Xcode 15) / gcc 13+, and if your distro's CMake is older than 3.24,
pip install cmake or brew install cmake gets a current one everywhere. Nothing else —
tree-sitter's core, the grammars listed in THIRD_PARTY.md and the test framework are vendored under third_party/deps,
so there is no download step and no package manager to satisfy. Prove that with the network off:
add -DFETCHCONTENT_FULLY_DISCONNECTED=ON and the build still completes.
Two builds, two jobs — pick by what you are doing:
# building to USE it — the fast binary (Release implies LTO; scripts/pgobuild.sh adds PGO, what CI ships)
cmake -S . -B build-release -DCMAKE_BUILD_TYPE=Release && cmake --build build-release -j

# building to WORK ON it — plain configure, no build type (why that matters: the trap, under the fold below)
cmake -S . -B build && cmake --build build -j
See Languages for supported source and document formats.
To put it on PATH, ./install.sh builds and atomically installs the binary plus the matching
skills/ and hooks/ assets into a detected prefix (Homebrew's if present, ~/.local otherwise;
override with RIPWIRE_INSTALL_PREFIX). Set RIPWIRE_ACTIVATE_CODEX=1 to also refresh Codex's skill
links and advisory hooks from that same staged version; activation is otherwise explicit.
Wiring it into your agent takes one more minute — wrap prints the recipe for your client, it
never edits your config:
ripwire wrap claude             # prints the wiring: the CLI call first, `claude mcp add` as the alternative
ripwire wrap --all              # detect every installed agent, print each one's recipe
skills/install.sh --codex       # Codex CLI: the task-shaped skills that say when to query — and when to stop
Four commands worth learning first:
ripwire . --max-tokens=3000                        # the ranked map — start here (bare it is ~22 KB / ~9K est_tokens on this repo; this keeps the head at ~6 KB / ~2.5K)
ripwire . --for="incremental cache invalidation"   # the task lens: what to touch, ranked
ripwire . --callers=someFunction                   # who calls it
ripwire . --test-gate                              # before you commit: which tests must run
Written for your agent. By default, every command prints compact XML sized for an AI agent to read, not for a person
scanning a terminal. Human-readable output is on the roadmap.
CLI or MCP, the -DCMAKE_BUILD_TYPE=Release trap, and the honesty contract in one line
The CLI is the recommended baseline because it works in every shell-capable agent; the MCP server is
optional, for agents whose workflow benefits from persistent tool registration. Full walkthrough,
all six clients: Agent setup.
The trap, spelled out: never configure the dev tree (build/) with
-DCMAKE_BUILD_TYPE=Release. Release defines NDEBUG, which compiles the degrade-path alerts out
and blinds the gates that assert them — and every gate and bench number is measured against
build/, so changing that tree's flavour silently moves all of them at once. Release belongs in
its own tree (build-release/ above; ./install.sh builds its own build-install/ the same way).
CI builds both flavours on purpose — see CONTRIBUTING.md.
The honesty contract, in one line: every count ripwire cannot prove is a total ships labelled a
floor, every truncation is disclosed where it happens, and a zero means none found — never none
exists. Two runs over the same tree are byte-identical, and a warm run equals a cold one. That is a
contract, gated on every pull request and every push to main, not a tendency.
The full discipline — and the losses published next to the wins →
The quality panel
4,956 eligible functions on this repository, and 2-of-6 agreement leaves 401 worth a second look — an 8.1% shortlist
Six independent evidence families, ranked by how many of them agree — never one blended score.
Pointed at this repository's 4,956 eligible functions, 2-of-6 agreement leaves 401 worth a
second look: an 8.1% shortlist. Pooled over five corpora (n = 27,889) no two families correlate
above +0.168, which is what makes agreement corroboration rather than one metric counted twice.
What each family actually looks at — on this repository's own source, not a synthetic example:
| Family | Question | Backing verb | On this repo |
|---|
| structural | shape: complexity, size, nesting and how much of the body is deep, params, local-variable count — absolute bars, not a ranking | --metrics | buildGraph (src/graph.h:462): ccx=698 loc=1244 nest=8 humps=30 deep=283 locals=114 — 114 local variables invisible to every quality lens until this session, because naming/size analysis has always stopped at a function's signature; locals= is a disclosed floor (locals_floor="1"), threaded through the same walk that already computes ccx/nest, at zero extra parsing cost |
| lexical | identifier text: the 10 naming-* lint rules (short, wordy, case-mixed, uninformative, …) | --lint, --naming-consistency, --lint --naming-locals | see below — the one family with a fix, not just evidence |
| confusion | syntactic idiom: the 7 atom-* rules (implicit predicates, nested ternaries, embedded ++/--, …) | --lint | corpus-wide finding counts, not a per-function claim to spotlight here |
| historical | git change frequency — score = churn × cognitive complexity | --hotspots | src/main.cpp: churn=42 ccx=3387 score=142254 — top of --hotspots' ranking, and its own worst function (main, ccx=387) is where developers keep working and the code is hardest. One caveat the panel's own legend states and this table must too: churn is measured per file, so every symbol in a file carries that file's churn=/hrank= verbatim — this family is file evidence inherited by the row, never the row's own history |
| colocation (local reasoning) | how much you must read that isn't in front of you | --context-ratio | computeQualityDelta (src/mcpverbs.h:2031), ~50 lines, 87.0% of its distinct references resolve outside its own file — by the tokens a reader must actually read, 99.6%. A refinement of Beck & Diehl's per-class congruence (FSE 2011); Martin's instability I = Ce/(Ca+Ce) is its cruder ancestor |
| state (unintended side effects) | mutable state a change here can perturb, that --impact (who calls you) never asks about | --nonlocal-state | ensure_global_init (src/infra/profilePmc.h:288) reaches 3 distinct global/static cells through its own body and callees — a tiny, innocent-looking call site can still break state three hops away. Unsound by construction (no pointer aliasing, no indirect calls), so every count is a floor |
How the six families are joined, the churn caveat, and the nest= profile deep-dive
--quality-panel joins six independent evidence families (structural shape, lexical naming,
syntactic-confusion idioms, git churn history, cross-file colocation, and non-local mutable state)
and ranks by the count of families agreeing, never a weighted composite — averaging correlated
metrics and calling it several is the Maintainability Index's well-known failure mode. On this
repository the panel measures 4,956 eligible functions and narrows them to 401 worth a
second look at 2-of-6 agreement — an 8.1% shortlist, not a guess — and the largest correlation
between any two families, pooled across five independent corpora (n = 27,889), is +0.168: the
families really are measuring different things. The six-family table above shows what each finds on
this repository's own source; the sections below are the parts that need more than a row.
nest= is a max, so it cannot tell a long function from a tangled one
The structural family's nest= reports the single deepest line in a function. One line at depth 9 and
a thousand lines at depth 9 produce the same number — which means a long blocked-sequential body (a
run of shallow scoped steps, its max set by one inner loop nobody has to hold in their head) is
indistinguishable from a tangled one that sustains depth for hundreds of lines. Every consumer of
nest= inherited that blindness: the panel's structural family, --biggest-first's rank, the ensemble join.
--metrics now emits the profile beside the max — humps= (how many maximal regions reach the
nesting bar, CodeScene's "bumpy road": a rise above the threshold then a fall, so repeated missing
abstractions read differently from one deep tangle) and deep= (how many lines lie inside them, against
the loc= already on the row). Both come from the same fused walk that already computes ccx/nest, at
zero extra parsing cost; deep= is a disclosed floor (deep_floor="1"). Both are absent exactly when
nest < the bar — not-deep, never a hidden 0. deep counts lines and humps counts regions,
and two regions can share a line — a one-line if(c){x;}else{y;} at the bar is two regions on one line —
so deep below humps is legal output rather than a defect. On this repository's own source:
| function | loc | nest | humps | deep | deep/loc | reading |
|---|
ingest (src/ingest.cpp) | 1632 | 8 | 25 | 467 | 29% | genuinely tangled |
buildGraph (src/graph.h) | 1244 | 9 | 30 | 308 | 25% | genuinely tangled |
main (src/main.cpp) | 1061 | 6 | 29 | 111 | 10% | long, mostly shallow steps |
dispatchMcpLine (src/mcp.h) | 1099 | 7 | 22 | 102 | 9% | a dispatch table, not a tangle |
runDefaultMap (src/main.cpp) | 650 | 4 | 7 | 15 | 2% | blocked-sequential |
ur_walkTree (src/ingest.cpp) | 87 | 7 | 1 | 43 | 49% | small and tangled |
loc and nest alone rank main and dispatchMcpLine beside ingest and buildGraph; the profile
separates them, and it promotes ur_walkTree — 87 lines, so no size bar fires, yet proportionally the
densest thing in the table. This changes no ranking: humps > 0 is exactly nest >= bar, which is
precisely when the nest bar already fired, so the family count and the panel's shortlist are untouched.
It is strictly more evidence on rows that already appear — a reader can tell the two shapes apart without
opening the file.
The panel also carries one join, and it is deliberately not a seventh family: a row whose structural
evidence includes deep= (a body that sustains depth at the nesting bar) and that no indexed test
reaches is annotated join="deep+untested" — the pair where a refactor is most wanted and least safe,
put side by side because both facts are already on the row. It changes nothing: not fam=, not of=,
not the order, not which rows appear (counting it would be the structural family wearing a second hat).
The root reports tested_scope= (symbols any indexed test reaches — the join's honest denominator) and
deep_untested= (rows carrying the annotation across the whole row set); at tested_scope="0" no
indexed test reaches anything here, so "untested" would be a fact about what was crawled rather than
about the code, and the annotation is emitted on no row.
Five lenses sit beside the six-family join — deliberately outside its vote. Each is out for a
stated reason, not an oversight:
| Lens | Asks | Why beside the join | On this repo |
|---|
--field-affinity | which struct fields are read together but declared far apart; each loop's access shape (index vs pointer-chase) | its subject is a type, not a function — attributing a struct's finding to the functions touching it is a claim the lens never makes | MainDispatch: 12 findings at separation cost 92.88; 1,374 loops classified, 5 genuine pointer-chases |
cache-* lint rules + --with-profile | cache-hostile access shapes (alloc-in-loop, p=p->next, a[b[i]], node containers, …), then which are measured hot | rows are facts about sites, joined to per-scope hardware counters — not per-function evidence a family vote could count | aggressive rules: 0 hits in shipping src/; 327 findings adversarially triaged → 0 fix-worthy; the one open refactor settled by measurement (5.2 ms) |
--biggest-first (was --readability) | orders by Halstead volume, Posnett sigmoid (a size proxy — the readability-ordering claim is withdrawn) | the fitted score saturates past 20 lines — only the ordering is meaningful, and an ordering cannot vote in a count | ordering only, never a grade |
--naming-consistency | off-convention names, each with a computed propose= | the one lens that emits advice — a fix is not evidence, so it does not vote | camelCase dominant at 93.0%; 136 names flagged with proposals |
--lint --naming-locals | the naming rules pointed at local variables inside already-flagged functions | opt-in and unvalidated — stays outside any join until a real-corpus audit clears it (the withdrawn-rule lesson) | +973 findings that were structurally invisible before |
The depth on each lens — citations, caveats, and the withdrawn-rule note
Two verbs sit beside the panel, not inside its six-family join — worth knowing the boundary
rather than blurring it:
--field-affinity (cache-friendly co-access) is explicitly not a panel family, by unit: it
measures which struct fields are read together but declared far apart, and its subject is a type,
not a function — attributing a struct's finding to the functions that touch it would be a claim the
lens itself never makes (docs/EVALS.md §9.9.2). MainDispatch (src/main.cpp:1335, the 144-byte
struct threaded through nearly every verb) still carries 12 real findings against a separation
cost of 92.88 — fields read together in the same call routinely cross cache-line boundaries.
Chilimbi, Davidson & Larus's cache-conscious structure definition (PLDI 1999), validated on real
hardware counters; the advice-not-transform posture (report a split, never auto-reorder a struct)
follows Hundt, Mannarswamy & Chakrabarti (CGO 2006). This is a genuinely rare kind of tool: code
review catches cache-unfriendly patterns constantly, but every adjacent tool that reasons about
memory-access shape (Intel Advisor's pattern classifier, DMon, PerfLint) does it by running the
program first — a two-round adversarial literature and patent search found no shipping tool and no
published work that does this statically, before a line executes (tier: RARE BUT REAL, the full
citation trail and hedged claim wording in docs/LINEAGE.md). The same verb now
also classifies each loop's access shape — index/handle-based (predictable, the hardware
prefetcher can hide the latency) vs. pointer-chase (data-dependent, no struct layout fixes an
unhideable per-hop stall) — and, for genuine chases, checks whether the pointer you dereference to
reach the next node sits next to the payload you're about to read, since that cache-line fetch is
unavoidable and colocating there is a strictly higher-value fix than generic field reordering. On
this repository: 1,374 loops classified, 5 genuine pointer-chases found in a codebase
deliberately built handle-based rather than pointer-linked (guardrail G2) — the lens staying quiet
on code written to avoid the problem is itself a check that it isn't firing at random. Ships
entirely report-only: an A/B benchmark against a real 64 MB shuffled linked list measured a
mostly-null result, so the ranking-affecting half of this feature is a provable no-op until a
blind real-corpus validation session clears it — reported here at the same honesty level as
everything else in this table, not oversold ahead of the evidence.- The
cache-* lint pack + --with-profile (cache-friendly access patterns — the other half
of the locality story, shipped 2026-08-07/08) covers what --field-affinity deliberately does not:
eight AST shapes practitioners agree hurt — node-based containers, vector<T*>/vector-of-indirect
(the "matrix as vector of vectors"), heap allocation inside loops, p = p->next chase advances,
a[b[i]] gather subscripts, by-value shared_ptr parameters, and existing manual prefetches
flagged for re-measurement — loop-fenced by span algebra, C-family only, facts never verdicts. The
honesty numbers, both directions: on this repository the aggressive rules fire only in benches
and test fixtures, zero in shipping src/ (guardrail G2 holding is itself the check the rules
aren't firing at random), and a 13-agent adversarial triage of all 327 findings confirmed zero
as fix-worthy — every plausible refactor died on "win unmeasurable without a profile". That gap is
exactly what --lint --with-profile=FILE closes: it joins a RIPWIRE_PROFILE build's own
per-scope hardware counters (#PROF_TSV) onto findings, so a row carries heat_total_ms /
heat_l1d_mpki from a real run — static shape × measured PMU weight, the two halves of SYZYGY's
advice mode (Hundt, CGO 2006) finally in one command. Worked example: the one surviving refactor
candidate (flattening the Louvain adjacency) was settled by its new PROFILE_SCOPE in a single
measured run — 5.2 ms, 5.9% of the verb — a wasted afternoon prevented by a number
(docs/CACHELINT.md holds the full catalog, the wave-2 specs, and the
compiler-handled myths deliberately not checked).
--biggest-first (renamed from --readability, which still works — a stderr note points scripts at
the new spelling) is a sibling lens, not a panel family either — the one classic model in the tree
with a published closed form: Halstead volume (Halstead, Elements of Software Science, 1977) and
the Posnett/Hindle/Devanbu sigmoid fit (MSR 2011, doi:10.1145/1985441.1985454),
fitted on snippets of 20 lines or fewer — past that the fitted score saturates and only the
ordering stays meaningful, which is exactly how the verb is used: largest-first, never as a
grade. Halstead's volume specifically (not the later, less-trusted difficulty/effort derivatives) is
among the metrics shown to track measured cognitive load directly (Peitek, Apel, Parnin, Brechmann &
Siegmund, ICSE 2021, doi:10.1109/ICSE43902.2021.00056) —
--biggest-first emits volume and stops there; difficulty and effort are computed nowhere in this
tree. A ranking lens, never a grade, and here is what it actually orders: on ripwire's own
history at the pinned v0.6.2 tag (412 function pairs mined from 80 refactor/simplify/cleanup
commits), the order between two versions of a function followed the sign of its token-count change
in 96.0% of pairs — read a move as more or fewer tokens, not as more or less readable. Of the 412,
154 (37.4%) ran the commit's implied direction and 258 (62.6%) ran opposite it; Halstead volume drove
91.1% of those 258; a separate self-consistency check confirms the formula
computes exactly what it says it computes, so this is a construct-validity finding about the
ordering claim, not an arithmetic bug. (First recorded as 484 pairs / 30.2% from an unpinned git log --all walk that does not reproduce — full derivation, the instrument fix and the retracted
figure: docs/EVALS.md §8.) WITHDRAWN: the ordering claim is withdrawn —
stratified into narrow token-count bands, the later-fix association disappears in 8 of 10 deciles
(CIs include 1), so the order this verb produces is better explained as a residual size proxy,
measured in the lens's own units, than as an independent readability signal (derivation:
docs/EVALS.md §8). The lens's computation is unchanged pending a proper human
study, and --help=--biggest-first carries the same figures where a CLI reader meets them.--naming-consistency is the lexical family's one exception to "evidence, never advice": every
other lens in this panel tells you WHAT is wrong, never a computed fix. Case-style consistency is
the one property with a corpus-derivable answer — on this repository's src/, camelCase is the
dominant convention at 1,677/1,803 (93.0%) agreement, and the verb flags 136 off-convention
names with a mechanically recombined propose= value for each (no dictionary, no synonym judgment —
see What it answers).--lint --naming-locals points those same naming rules at local variable names — the thing a
human reviewer flags immediately in a sprawling function and no static tool measured until this
session. Opt-in, off by default: on this repository, a plain --lint finds 2,225 findings;
adding --naming-locals finds 3,198 — 973 findings that were structurally invisible
a moment ago, scoped tightly (only inside functions already flagged large/complex, only locals
nested two blocks deep for the short-name rule) so it doesn't just relabel every loop counter in
the tree. Ships disabled by default on purpose: this repository's own history includes a naming
rule that shipped on plausibility and was later measured to flag its best-named functions — see
the withdrawn-rule note below — so a rule this new stays opt-in until a real-corpus audit clears it.
The full citation table, the evidence tiers, and the naming rule that was withdrawn for flagging this repository's best-named functions
Full citation table, evidence tiers, and what got measured and withdrawn (a naming rule that
flagged this repository's best-named functions, kept as the standing argument for measuring before
shipping) → docs/LINEAGE.md.
Want to help? Start anywhere on the spectrum. At the ready-made end, open problems — languages,
resolver bugs, fuzzers, docs


 0x4m4/hexstrike-ai13k


